
kappa
KAPPA: Kit of Agents for Proof-checking Papers with a proof Assistant. Checks the proofs in LaTeX papers with Lean 4 and Claude Code agents.
Install with your AI
Paste into Claude Code, Cursor, or any agent — it reads the repo and wires the tool into your project.
Install and set up kappa (release-binary project) into my current project.
Found on https://claudeers.com/kappa
Repo: https://github.com/ziwaa-se/kappa
Homepage/docs: https://arxiv.org/abs/2610.35596
Detected install method: release-binary → inspect the README
Category: other. Platforms: cli, desktop.
Read the repo's README for exact setup and env vars, then install it and wire it into my project.

Claudeers Health Verdict:
active; community-verified: false. Confirm the source before running anything.
Grab the latest release asset from GitHub.
# download a build from https://github.com/ziwaa-se/kappa/releases
git clone https://github.com/ziwaa-se/kappa
// compatibility
| Platforms | cli, desktop |
|---|---|
| Operating systems | — |
| AI compatibility | claude |
| License | MIT |
| Pricing | open-source |
| Language | Lean |
KAPPA
Kit of Agents for Proof-checking Papers with a proof Assistant, released as the TeX Proof-Check Kit up to v1.3.4.
Paper: arXiv:2610.35596 · How to cite
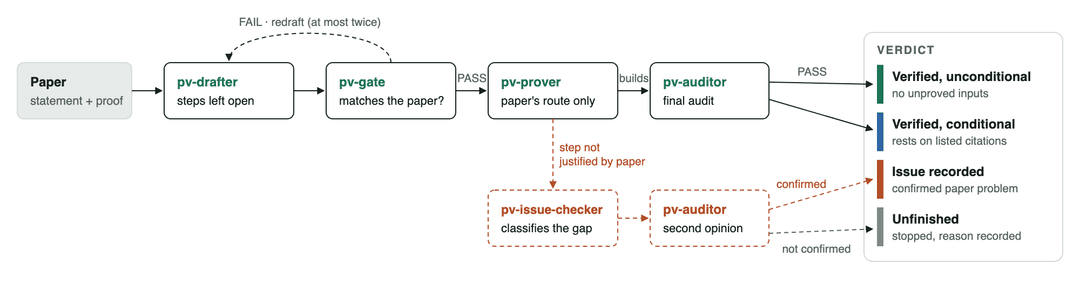
Check the proofs already written in a LaTeX paper by translating them faithfully into Lean 4, with a team of Claude Code agents that review each other's work. Every numbered result (theorem, proposition, lemma, corollary) gets one of four verdicts:
| Verdict | Meaning |
|---|---|
| Verified unconditionally | The paper's own proof compiles in Lean, with no unproved input |
| Verified conditionally | It compiles, but relies on results the paper cites or does not prove. These are explicit, named Lean hypotheses that a person should check |
| Issue recorded | A confirmed problem, located in the paper and classified by whose fault it is: false statement (ERROR), a justification that fails, a missing hypothesis, an uncovered case, an ambiguous domain |
| Unfinished | Stopped, with the reason recorded. Never counted as an error in the paper |
Scope of this version. The kit verifies proofs that are already written. It checks the argument the authors wrote, step by step, and reports exactly where it holds and where it fails. It does not repair proofs, search for different proofs, or edit the paper. When it finds a problem, it records the evidence and the minimal change that would remove it; when the authors revise the paper, it re-checks the changed results. A mode that also proposes and verifies corrections is planned; see the Roadmap.
Example
examples/full-workflow is a two-page note with three results, taken through the whole workflow: a first check, a corrected version of the paper, a condition checked by a person, and the final report. Real output of one run:
| Result | First check | After the authors' revision and a person's check |
|---|---|---|
| Lemma 2.1: $ab \le \frac{a^2+b^2}{2}$ | Verified unconditionally | unchanged (not re-checked: the lemma did not change) |
| Proposition 2.2: a refinement of Nesbitt's inequality | Verified conditionally: relies on the cited Nesbitt inequality, an explicit Lean hypothesis | Verified conditionally; conditions checked by a person. A person's check is recorded, but only a Lean proof would make it unconditional |
| Lemma 2.3: $\frac{x^2}{1+x} \ge x-1$ for $x \neq -1$ | Issue recorded (ERROR): false for $x < -1$; Lean counterexample at $x=-2$, independently reviewed | The authors changed the hypothesis to $x > -1$. Only this lemma was reset (unfinished until re-checked), then verified unconditionally; the issue is marked resolved |
-- Lemma 2.3 as first printed, and its machine-checked refutation
def PrintedClause : Prop := ∀ x : ℝ, x ≠ -1 → x ^ 2 / (1 + x) ≥ x - 1

theorem counterexample : ¬ PrintedClause := by
  intro h
  have h2 := h (-2) witness_satisfies_printed_hypothesis
  norm_num at h2

-- Proposition 2.2: the cited result is a named hypothesis, never a hidden axiom
theorem P01_main (hN : NesbittInequality) (x y z : ℝ)
    (hx : 0 < x) (hy : 0 < y) (hz : 0 < z) : P01Conclusion x y z
The four steps took 57, 17, under 1, and 20 minutes ($34 in total at list price). The progress table at each stage is in TIMELINE.md. Both reports (before and after the revision), the Lean files and every audit are in the example folder.
A shorter example, examples/two-lemmas-demo, has one lemma that is verified and one with a planted error. It takes about 22 minutes, and is the one to run first.
Examples with answer keys
Four short papers were written to exercise every verdict and issue class, each with an answer key fixed before its run. Each folder has the paper, the key, the run's complete record and a README with the score, the cost and the time (v1.3.1, October 2026).
| Example | What it tests | Verdicts as in the key, or an outcome it allows | Time, cost |
|---|---|---|---|
e1-sample-variance | a false lemma with a counterexample, a cited inequality, an uncovered case, a corollary built on the false lemma | 5 of 6 (the sixth: the kit found a second, real gap) | 82 min, $14.54 |
e2-proportions | an ambiguous interval, a "well known" fact, a false lemma, quantifier order, a step needing a missing hypothesis | 5 of 6 | 75 min, $14.74 |
e3-shrinkage | an argument gap in a true lemma, an inherited condition, then a revision through /pv-revise | 4 of 4, and all verified after the revision | 71 + 23 min, $17.25 |
e4-edf | the edge of Mathlib: a named but unproved theorem, a statement that needs a Brownian bridge | 3 of 3 | 81 min, $14.32 |
How it works
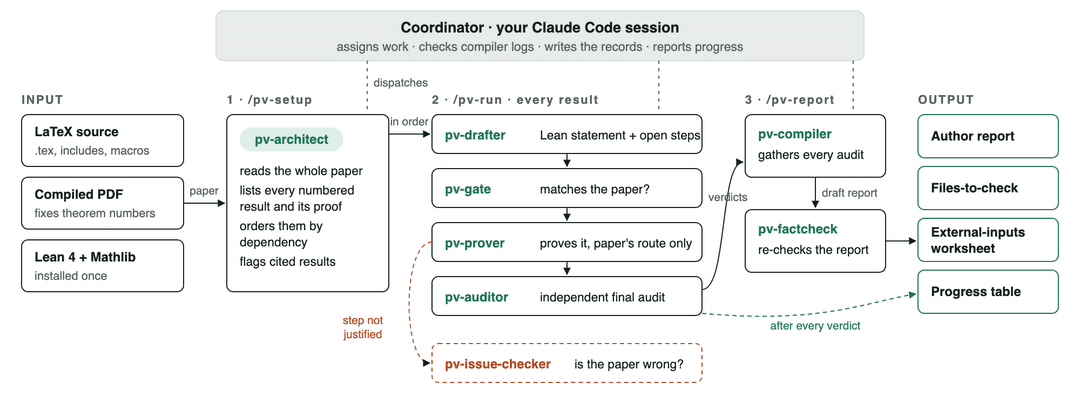
Each result goes through separate agents, and none of them reviews its own work:
-
Statements are checked before proofs. A gate agent compares the Lean statement with the paper (hypotheses, quantifiers, domains, constants) before any proving starts. Its fingerprint of the statement is checked again at the end, so the statement cannot drift.
-
Only the paper's route. The prover follows the paper step by step. Where the paper gives no valid justification, it stops; it does not invent a fix.
-
Independent final audit. The auditor recompiles everything privately, and checks that the statement is unchanged, that only the three standard axioms are used, and that there is no
sorryanywhere. It also checks which hypotheses each theorem really uses, and whether each step follows the paper. -
Problems are double-checked. A suspected error goes to an issue-checker, which builds a Lean counterexample when it can; a second auditor reviews the ruling. A compile failure alone never counts as an error in the paper.
-
Cited results stay visible. What the paper cites or assumes without proof becomes an explicit
def … : Prophypothesis, listed for a person to check, never a hidden axiom. -
The report is fact-checked. An independent agent checks the final report against the records before you see it.
-
Who may write what is enforced. A hook checks every write (v1.3.1): nobody writes outside the project, the coordinator never edits a proof, and reviewers never edit what they review. The mechanical audit report names who ran it.
Records are plain files (RESULTS.json, Markdown reports, Lean files), so work survives usage limits and closed windows (/pv-resume). The unattended driver waits out usage limits by itself (--auto-resume). After a revision, only the results whose statement, proof or definitions changed are redone; results that use them are rebuilt and re-checked mechanically when the statements they use did not change.
What you need
- macOS or Linux, with
gitandpython3(3.6 or newer); - Claude Code, in the Claude desktop app, the VS Code extension or the terminal, on a plan that includes it;
- about 10 GB of disk space for Lean 4.19.0 and Mathlib (installed once, with internet access);
- elan, Lean's installer. The guided setup can install it for you.
Quick start (guided)
-
Make a folder for your checks and put the kit in it:
mkdir -p ~/proofcheck && cd ~/proofcheck
git clone https://github.com/ziwaa-se/kappa.git
(Or download a ZIP: Code → Download ZIP on this page, or Source code (zip) under the latest release. Unzip it in
~/proofcheckand rename the unzipped folder (kappa-mainorkappa-1.4.0) tokappa, so that the sentence in step 2 works as written.) -
Open
~/proofcheckin the Claude desktop app or in VS Code, start a new Claude chat, and send:Read kappa/CLAUDE_START_HERE.md and follow it. -
Answer its questions. Claude checks your machine, installs Lean and Mathlib once (it asks before downloading anything), and makes a new folder for your paper (
papers/<name>-check/). It then helps you put the paper's files in (.tex, inputs, the PDF and the.aux) and tells you how to start the check. That last step happens in a new chat opened in the paper's folder, where the kit's agents live.
To try it on the example first, add: "I want to run the demo paper: call it demo. The files are in kappa/examples/two-lemmas-demo/paper."
Prefer to do it by hand? See docs/QUICKSTART.md.
Everyday use
Always start the same way: open ~/proofcheck, start a new chat, send the sentence above, and add what you want:
| You want to | Add |
|---|---|
| Check a new paper | "I have a new paper; call it <name>." |
| Continue after a usage limit or a closed window | "Continue <name>." (or /pv-resume in the paper's chat) |
| Re-check a corrected version | "My paper <name> has a revised version." Only the changed results, and those depending on them, are re-checked; earlier issues are marked resolved only by a new audit. |
| Record that you checked a cited result yourself | "For <name>, I checked <condition> against <source>." The result stays conditional, now marked "conditions checked by a person". |
| Get the report | "Make the report for <name>." |
In the paper's own chat: /pv-status shows the progress table. /pv-resume continues after any interruption. /clear followed by /pv-resume keeps long runs cheap.
The full workflow, with tested prompt templates and a section on VS Code connected to a cluster, is in docs/GUIDE_EN.md. A one-page summary is docs/CHEATSHEET.md.
What you get
In papers/<name>-check/verification/report/:
| File | Content |
|---|---|
AUTHOR_REPORT.md | Summary table, each verdict, the issues for the authors with exact locations, typos, and what a person still has to check |
FILES_TO_CHECK.md | For each result: paper location ↔ Lean theorem (file:line) ↔ audit report |
EXTERNAL_TOOLS_WORKSHEET.md | Every cited or unproved input, with its exact Lean text, sorted by risk, with check boxes |
What only a person can do:
- check that the cited results are true;
- check that the basic definitions match the paper;
- check that each Lean statement says what the paper says.
The Lean proofs themselves need no reading: the Lean kernel checked them.
Cost and speed
Runs use your Claude Code plan; the numbers below are list-price estimates.
| Paper | Time | Cost |
|---|---|---|
| Two-lemma example, both verdicts | ≈ 22 min | ≈ $9 |
| Full-workflow example: first check, revision, human check, report | ≈ 95 min | ≈ $34 |
| Three-result benchmark, three verdicts (v1.3, two runs) | 30–51 min | $14–18 |
| The same benchmark with the previous version, v1.2.1 | 83–84 min | $65–71 |
A research paper costs far more, and usage limits will pause long runs; /pv-resume continues them, and the unattended driver continues by itself after the reset. Every result needs several independent agents even when it is easy, so a fixed cost per result is part of the design. See bench/results/COMPARISON.md for how v1.3 cut the cost by about 77% without changing a verdict.
Limitations
- Conditional means conditional. A "verified conditionally" result is only as sound as its listed hypotheses. A person's check of a hypothesis is recorded, but it does not make the result unconditional.
- Statement fidelity is reviewed by agents, not proved. The gate and the auditor compare the Lean statement with the paper, but a person should still read the Lean statements listed in
FILES_TO_CHECK.md. - Pinned versions. Lean 4.19.0 and Mathlib
c44e0c8e. Newer versions should work but are untested. - Platforms. Developed and tested on macOS; also used on a Linux cluster through VS Code Remote-SSH.
- No network during checks. Agents may not browse or download, so cited works are never fetched. They are listed for a person to check.
- AI agents run commands. The kit runs Claude Code agents that compile and edit files in the project folder. The optional permission file (
.claude/settings.example.json) allows only the kit's own commands, forbids network access and edits to the paper, and installs the guard hook. Review it before enabling it. The hook and the kit's Lean IO check guard against mistakes; they are not a sandbox. - Re-check without a model.
examples/tools/replay.pyrebuilds a finished run's Lean files and reruns the mechanical audit at the pinned versions, so anyone can confirm the verdicts' evidence without Claude Code. - Tests.
tests/checks the scripts offline (no model, no network):python3 -m unittest discover -s tests. With a Lean environment,PV_TEST_LEAN_ENV=<lean-env>adds integration tests of the mechanical audit.
Repository layout
kappa/
├── CLAUDE_START_HERE.md      guided setup: what a new Claude chat follows
├── autosetup/                scripts for the guided setup (environment check, shared Lean, new project, ...)
├── install.sh                manual install of a paper project (--pinned / --lean-from / --upgrade)
├── template/                 what each paper project gets: CLAUDE.md, .claude/agents (8 roles), .claude/skills
│                             (/pv-setup, /pv-run, /pv-status, /pv-resume, /pv-report, /pv-revise), rules, scripts,
│                             PVTools.lean (audit commands: axioms, constant walks, statement fingerprints)
├── lean-pins/                the tested Lean and Mathlib versions
├── docs/                     GUIDE_EN, QUICKSTART, CHEATSHEET, MANUAL, diagrams/, lean-demo/
├── examples/
│   ├── full-workflow/        every verdict, a revision and a human check: the real output of one run
│   ├── two-lemmas-demo/      a 20-minute example to try first
│   ├── e1-…, e2-…, e3-…, e4-…  four papers with answer keys fixed before their runs, and the runs' records
│   └── tools/                replay a run offline, score it against a key, audit a blind run, sanitize a record
├── bench/                    benchmark paper, answer key, runner and measured results
├── replication/              the paper's replication materials: all seven cases, the comparison runs, replicate.sh
└── tests/                    offline tests of the scripts; Lean integration tests with PV_TEST_LEAN_ENV
Documentation
- docs/GUIDE_EN.md: the complete workflow, with prompt templates.
- docs/QUICKSTART.md: manual installation in one page.
- docs/CHEATSHEET.md: one page to keep next to you.
- docs/MANUAL.md: reference manual covering all options, the verdict rules and what can be adjusted.
- docs/lean-demo/: a two-minute introduction to what Lean checks.
- template/verification/rules/: the rules all agents follow: verdicts, issue classes, the pipeline and the audit methods.
- CHANGELOG.md: version history.
Paper
Zihua She and Xiao Wang (2026). KAPPA: Checking the Proofs in Statistics Papers with Lean 4 and Language Model Agents. arXiv:2610.35596. The paper describes the design, follows a complete run, applies the kit to four example papers with answer keys and to three published statistical papers checked blind before their corrections, and compares it with a direct use of the same language model.
replication/ holds the paper's replication materials: the records of every run, the answer keys,
the comparison runs and replicate.sh, which reproduces every table of results in a few seconds and, with
--replay <lean-env>, rebuilds every archived Lean file and reruns the mechanical audits in under an hour, all
without a language model. See replication/README.md.
Citing KAPPA
If you use KAPPA in your work, please cite the paper:
@misc{she2026kappa,
  title         = {{KAPPA}: Checking the Proofs in Statistics Papers with {Lean} 4 and
                   Language Model Agents},
  author        = {Zihua She and Xiao Wang},
  year          = {2026},
  eprint        = {2610.35596},
  archivePrefix = {arXiv},
  primaryClass  = {stat.CO},
  doi           = {10.48550/arXiv.2610.35596},
  url           = {https://arxiv.org/abs/2610.35596}
}
The "Cite this repository" button on GitHub, made from CITATION.cff, gives this reference in APA and BibTeX.
Roadmap
This version (v1.4.0) only verifies the proofs a paper already contains. Planned extensions, not yet available:
- Repair mode. After an issue is confirmed, agents would propose a correction: a missing hypothesis, a narrower statement, or a different argument for the failing step. They would verify it in Lean within fixed attempt and time limits, then pass it through the same independent gate and final audit. A repair would be reported separately and labeled as such. It would never change the verdict on the paper as written, and never be presented as the authors' proof.
- Completing unfinished steps. An optional, longer proof search for steps stopped by formalization difficulty (
TRANSLATION_BLOCKED,BUDGET_EXHAUSTED), also with limits. - Closing conditions automatically. When a cited result turns out to be available in Mathlib, prove and connect it so that a conditional verdict becomes unconditional. Today this is done by hand, in the same way as the reconnection of stage 6b.
Use cases and suggestions are welcome in the issues.
Contributing
Bug reports and suggestions are welcome; see CONTRIBUTING.md. When something fails, please include the output of autosetup/doctor.sh <your folder> and the relevant log from pv_work/logs/.
License
MIT. Copyright (c) 2026 Zihua She.
This project is not affiliated with Anthropic, the Lean FRO or the Mathlib community. It relies on Lean 4, Mathlib and Claude Code.
// faq
What is kappa?
KAPPA: Kit of Agents for Proof-checking Papers with a proof Assistant. Checks the proofs in LaTeX papers with Lean 4 and Claude Code agents.. It is open-source on GitHub.
Is kappa free to use?
kappa is open-source under the MIT license, so it is free to use.
What category does kappa belong to?
kappa is listed under other in the Claudeers registry of Claude-compatible tools.
// embed badge

[](https://claudeers.com/kappa)
// retro hit counter

[](https://claudeers.com/kappa)
// reviews
// guestbook
// related in Other
 🔓
 🔓
Anti-AI-slop design skill for Claude Code, Cursor, and Codex.
 🔓
Huashu Design · HTML-native design skill for Claude Code · Claude Code 里 HTML 原生的设计 skill · 高保真原型 / 幻灯片 / 动画 + 20 设计哲学 + 5 维评审 + MP4 导出 · Agent-agnostic
 🔓
Open source Ghostty-based macOS terminal with vertical tabs and notifications for AI coding agents. Built for multitasking, organization, and programmability.