
cheat-on-content
You're reading this. The skill predicted it. A workflow that turns every post into a calibrated experiment—score, blind-predict, retro, evolve. The future do…
Install with your AI
Paste into Claude Code, Cursor, or any agent — it reads the repo and wires the tool into your project.
Install and set up cheat-on-content (claude-skill project) into my current project.
Found on https://claudeers.com/cheat-on-content
Repo: https://github.com/XBuilderLAB/cheat-on-content
Homepage/docs: —
Detected install method: claude-skill → # copy this skill into .claude/skills/cheat-on-content/
Category: uncategorized. Platforms: mobile.
Read the repo's README for exact setup and env vars, then install it and wire it into my project.

Claudeers Health Verdict:
active; community-verified: false. Confirm the source before running anything.
# copy the skill dir into your project:
# .claude/skills/cheat-on-content/   (or ~/.claude/skills/cheat-on-content/ for all projects)
git clone https://github.com/XBuilderLAB/cheat-on-content
// compatibility
| Platforms | mobile |
|---|---|
| Operating systems | — |
| AI compatibility | claude |
| License | MIT |
| Pricing | open-source |
| Language | Python |
Cheat on Content
English · 简体中文
For content creators — a skill that turns every post into a calibrated experiment.
You're reading this. The skill predicted it.
It turns every "I feel this will go viral" into a calibrated experiment.
It took me from zero to 1M followers in a month. It said I'd write this. I did.
Your doubt — predicted too.
🎬 What it actually does
Most creators live in the same gambling loop:
Publish → Numbers come in → Learn nothing → Roll the dice again
A creator who's shipped 200 pieces is barely 10% sharper than someone who's shipped 1 — because they never kept books after each round.
Cheat on Content makes every judgment get logged, retrospected, absorbed into the next:
📊 Score → 🎯 Blind-predict → 🚀 Publish → 📈 T+3d retro → 🧬 Evolve your rubric
This isn't motivation. It's compounding — every piece you don't retro is silently eroding your ability to see yourself.
One month in = you have a hit-formula that's only yours. Three months in = you're 10× sharper than your first-day self.
🌀 Origin
I never believed in fate. Until this skill made me film a video — and predicted exactly how much traffic that video would pull.
I tried to break it. I told my audience. I hoped collective observation would collapse the wave function and shift the trajectory.
The data was accurate.
I didn't escape fate. I just moved from first-order to second-order.
If even my awakening — even my audience's observation — was already in its prediction, then right now, reading this: are you here out of curiosity, or just closing the algorithm's last move?
— the creator
⚖️ How it differs from other "creator tools"
| Others | This |
|---|---|
| Give you "inspiration" | Make your own intuition measurable |
| AI writes for you | AI judges for you — the script stays yours |
| Ship 10 versions, A/B test | Ship one — bet in writing, settle the books with data |
| Static dashboard | An evolving rubric — your formula 3 months from now isn't the starting one |
In a sentence: other tools help you "ship more." This helps you "judge sharper."
🤔 Can't I just use ChatGPT / DeepSeek / Doubao?
Those are general assistants — they tell everyone the same thing. You ask "will this go viral?" and the answer is fitted to global average opinion, not your channel. Ask again tomorrow — same answer. It doesn't remember you. It doesn't change because of you.
This is your own ops expert — serving only your one channel:
- The scoring formula is reverse-engineered from your history, not the global training distribution
- Every piece you ship updates its understanding — by month three, judgment accuracy is 10× sharper than day one (auto-evolving)
- It knows your benchmark account, your cadence, the last three reasons you flopped — things ChatGPT forgets after the first reply
General LLMs help everyone. This helps your account.
🛡️ Why the loop actually evolves
📝 Every piece is logged: Score and prediction get written before publish, archived end-to-end. Three days later you settle accounts — you see exactly where you were sharp, where you were off. No more vague "I feel this one didn't land."
🔁 It gets sharper: Three same-direction misses in a row, the tool actively prompts you to upgrade your scoring formula. You don't have to remember — it remembers for you.
🛡️ Upgrades have a brake: Switching the formula requires re-scoring all historical samples — only released if it ranks more accurately than the old. Plus a cross-model independent audit — so you can't fool yourself.
🪒 The rubric is a workbench, not a museum: Observations refuted by data get deleted; observations absorbed into formal dimensions also get deleted. It only holds what's most useful right now.
📦 Install
git clone https://github.com/XBuilderLAB/cheat-on-content.git
cd cheat-on-content
bash install.sh
⚠️ Upgrading from v0.x? Run
/cheat-migratein your content project aftergit pull. The 1.3 → 1.4 migration is BREAKING for blind-channel integrity — it splitsrubric_notes.mdso the blind sub-agent can't leak actuals. Without migrate, blind scoring will keep flaggingnon_blind_warning. See CHANGELOG and migrations/1.3-to-1.4.md.
14 sub-skills are symlinked into your agent's skill directory. One install, every content project gets it.
Supported agents: Claude Code (default) · Codex (bash install.sh --codex) · Both (bash install.sh --all)
Frozen version:
bash install.sh --copy/bash install.sh --codex --copyUninstall:
bash uninstall.sh/bash uninstall.sh --codex(your content data is not touched)
🚀 First run
In your content project directory, open a skill-compatible agent and say:
初始化 cheat-on-content
(or init cheat-on-content)
Five yes/no questions complete onboarding. Strongly recommend importing a benchmark account — 5–10 samples and the tool gets an anchor immediately. Without one, your first 5 predictions land at ±50% precision.
⚡ Daily use
score this scripts/<...>.md       → grade only
start prediction scripts/<...>.md → blind prediction + decision log
shot scripts/<...>.md             → create video folder + buffer +1
shipped https://...                → buffer -1
retro videos/<...>/                → T+3d data + retrospective
status / fetch trends / find topic / bump rubric / find benchmark
Hook-aware agents auto-report buffer + pending retros + top candidates at every session start — no need to ask. Other agents: just say status.
Full workflow + sub-skill details: see SKILL.md.
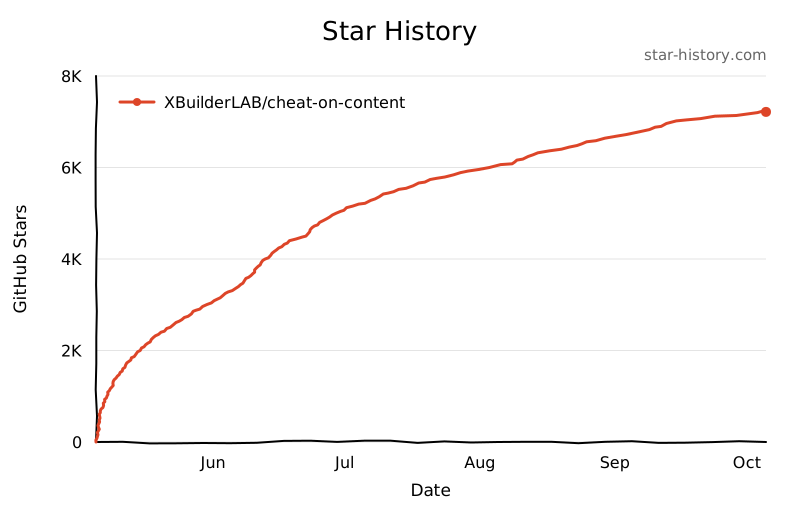
📈 Star History
📜 License
MIT. Commercial use, modification, closed-source integration — all fine.
Is this cheating? So was the calculator. So was Google. The future doesn't reward effort — it rewards those who see the pattern first.
You reading this line — that's predicted too.
// faq
What is cheat-on-content?
You're reading this. The skill predicted it. A workflow that turns every post into a calibrated experiment—score, blind-predict, retro, evolve. The future doesn't reward effort, it rewards those who see the pattern first. 1M followers in a month — not luck, system.. It is open-source on GitHub.
Is cheat-on-content free to use?
cheat-on-content is open-source under the MIT license, so it is free to use.
What category does cheat-on-content belong to?
cheat-on-content is listed under uncategorized in the Claudeers registry of Claude-compatible tools.
// embed badge

[](https://claudeers.com/cheat-on-content)
// retro hit counter

[](https://claudeers.com/cheat-on-content)
// reviews
// guestbook
// related in Uncategorized / Others
 🔓
Fair-code workflow automation platform with native AI capabilities. Combine visual building with custom code, self-host or cloud, 400+ integrations.
 🔓
The agent engineering platform.
 🔓
FULL Augment Code, Claude Code, Cluely, CodeBuddy, Comet, Cursor, Devin AI, Junie, Kiro, Leap.new, Lovable, Manus, NotionAI, Orchids.app, Perplexity, Poke, Q…
 🔓
100+ AI Agent & RAG apps you can actually run — clone, customize, ship.