
AISafetyHot
AI Safety HOT: daily AI safety news, papers and incidents in one place — jailbreaks, prompt injection, alignment, evals, governance. Website, daily digest, R…
Install with your AI
Paste into Claude Code, Cursor, or any agent — it reads the repo and wires the tool into your project.
Install and set up AISafetyHot (claude-plugin project) into my current project.
Found on https://claudeers.com/aisafetyhot
Repo: https://github.com/wuyoscar/AISafetyHot
Homepage/docs: https://aisafetyhot.com
Detected install method: claude-plugin → /plugin install aisafetyhot@wuyoscar/AISafetyHot
Category: uncategorized. Platforms: cli, api, web.
Read the repo's README for exact setup and env vars, then install it and wire it into my project.

Claudeers Health Verdict:
unknown; community-verified: false. Confirm the source before running anything.
⚠ Unverified / not recently updated — review before pasting a run-this config.
/plugin marketplace add wuyoscar/AISafetyHot
/plugin install aisafetyhot@wuyoscar/AISafetyHot
git clone https://github.com/wuyoscar/AISafetyHot
// compatibility
| Platforms | cli, api, web |
|---|---|
| Operating systems | — |
| AI compatibility | claude |
| License | NOASSERTION |
| Pricing | open-source |
| Language | TeX |
AI Safety HOT
追踪 AI 安全新闻、论文与事件。一站阅读,也能接入你的 Agent。
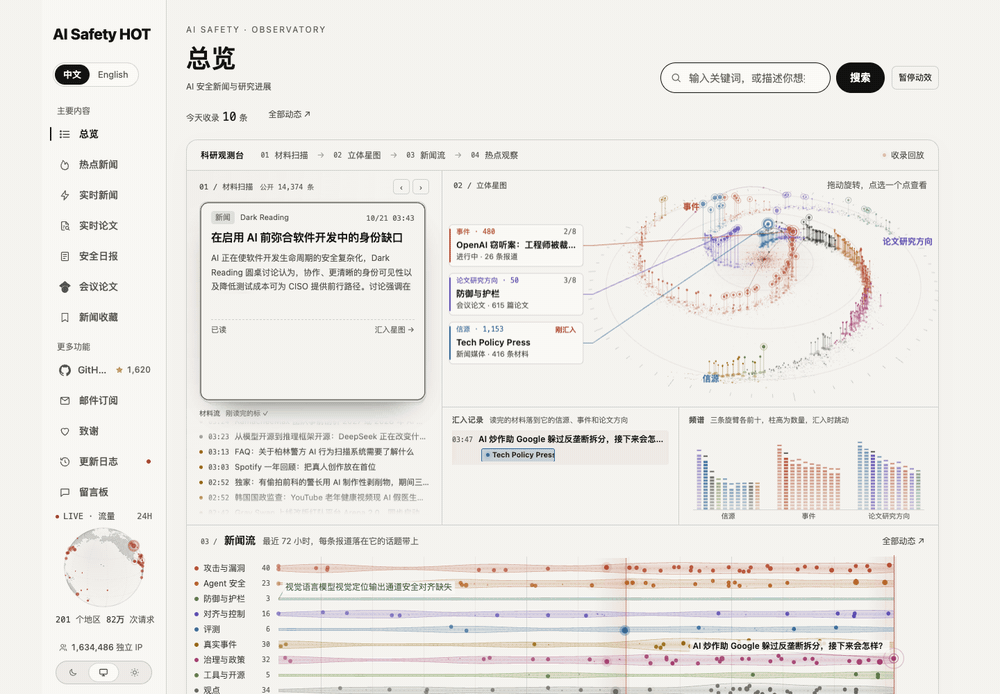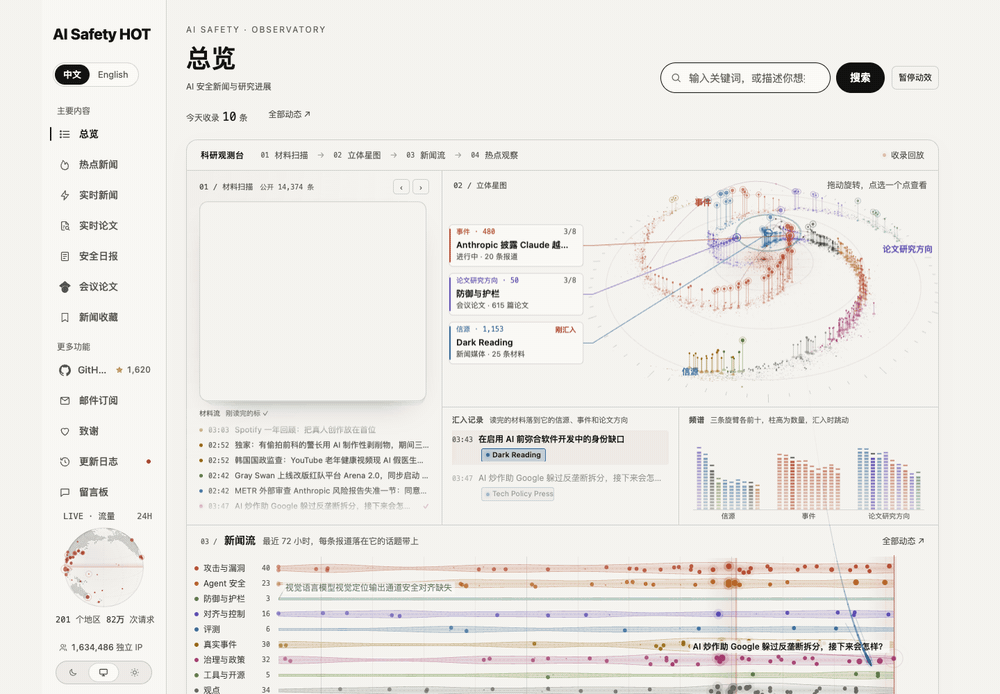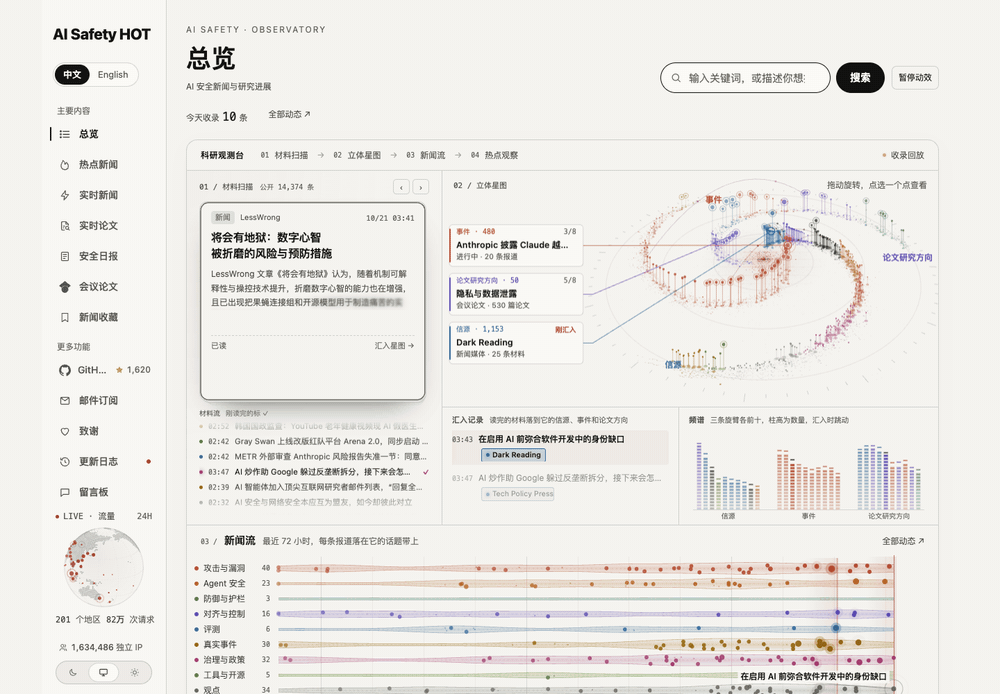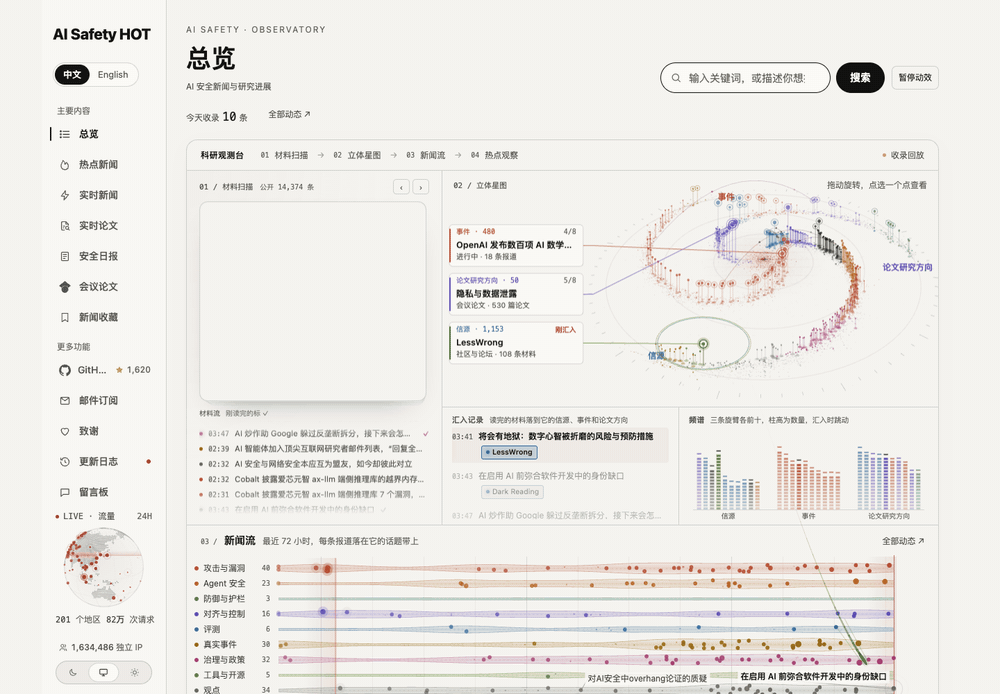
打开观测台 · 实时新闻 · 找论文 · 读日报 · 接入 Agent
AI Safety HOT 持续整理越狱、提示注入、Agent 安全、防御与护栏、对齐、评测、真实事件和治理政策。网站提供中英文阅读;这个 Hub 保存公开论文清单、日报归档和 Agent 技能。
从一条动态,看到它关联的研究与事件
首页是一座可以探索的科研观测台:材料卡片逐条扫描,汇入由信源、事件和论文研究方向组成的立体星图;往下是最近 72 小时的新闻流,以及汇集报道与社区讨论的热点观察。拖动星图旋转,点选节点,沿链接继续阅读。
上面的 GIF 来自真实网站录屏。查看高清静态图 · 查看新闻流与热点观察
| 想看什么 | 从这里开始 |
|---|---|
| 最近发生了什么 | 实时新闻:浏览动态、阅读导读,回到原文。 |
| 一件事怎样发展 | 热点新闻:把相关报道放在一起,查看事件进展与讨论。 |
| 一个方向有哪些研究 | 实时论文与会议论文:按研究方向筛选,查看题录、速读和原文。 |
| 每天集中读一遍 | 安全日报:按方向整理,当天的新进展补进同一期。 |
展开新版页面截图
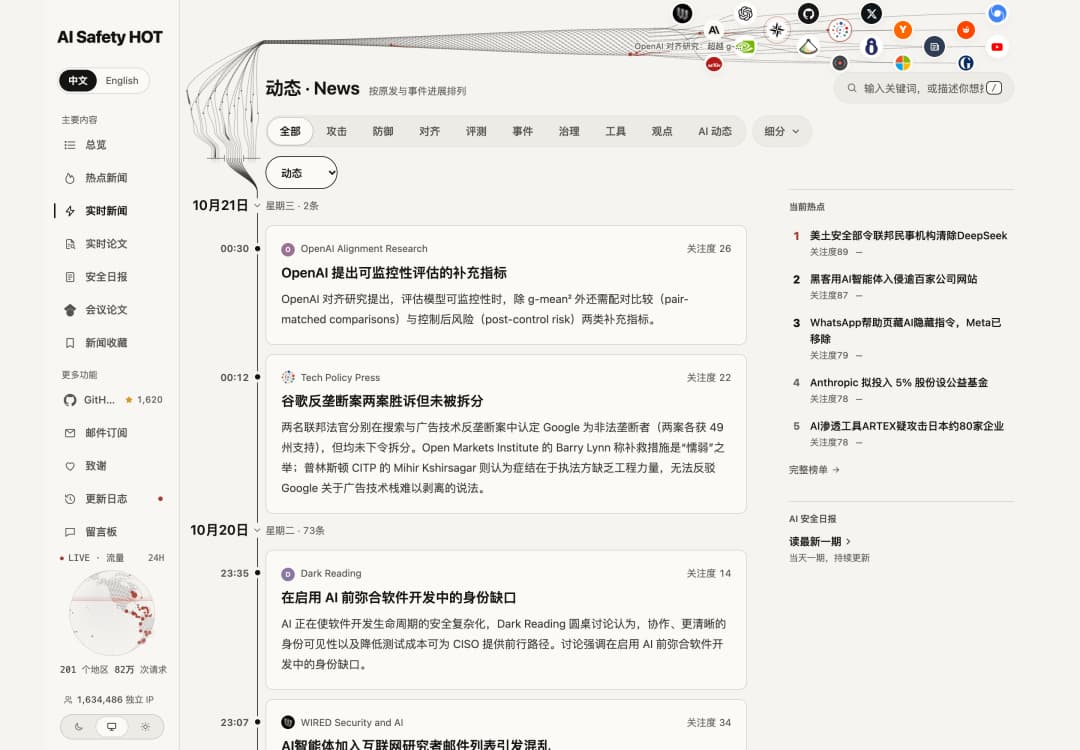
实时新闻
按时间浏览新闻,结合搜索与筛选找到你关心的动态。
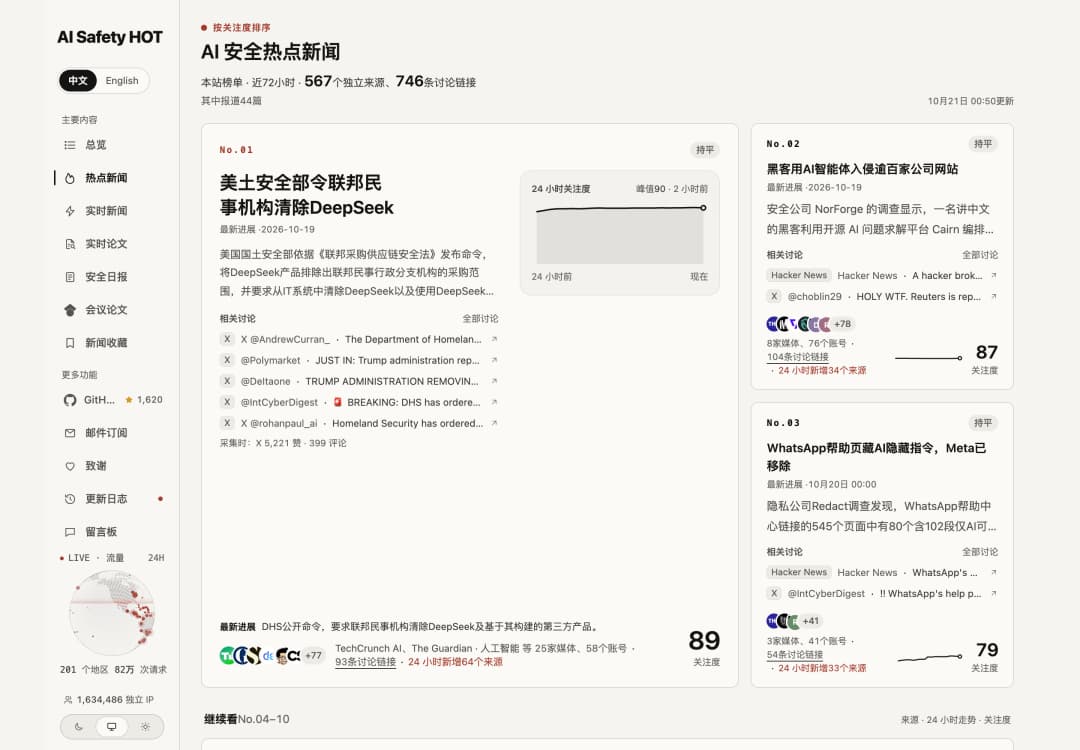
热点新闻
从一个事件进入,查看相关报道和讨论。
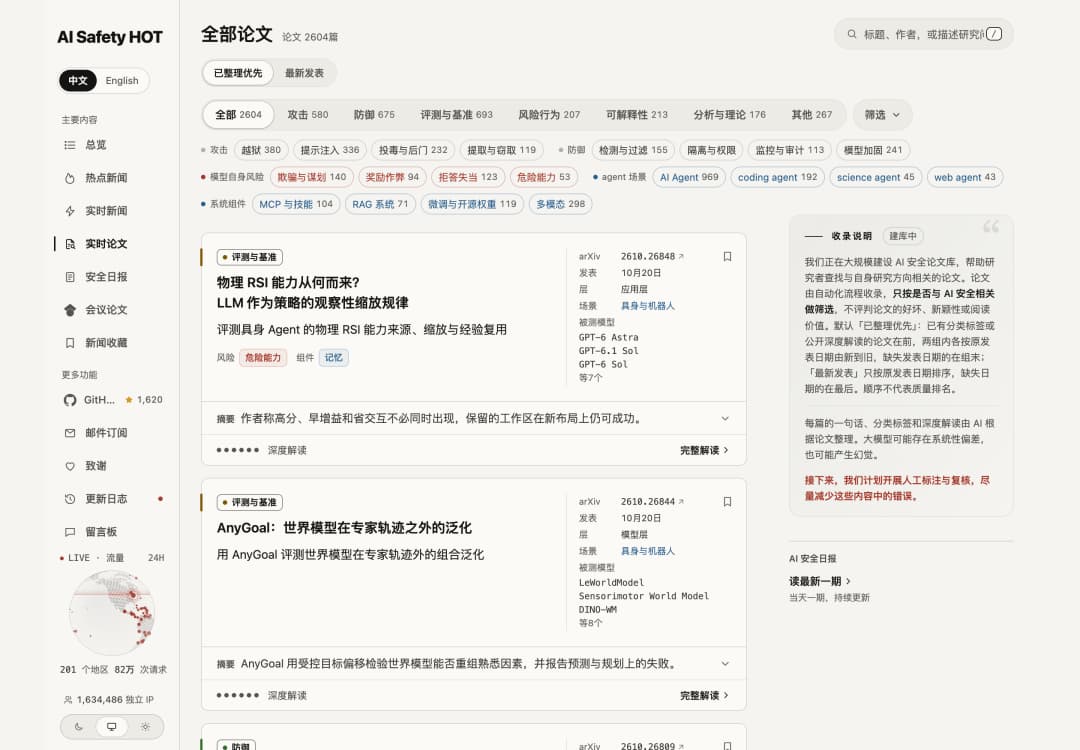
实时论文
按研究方向、论文类型和 Agent 场景筛选,继续阅读速读与原文。
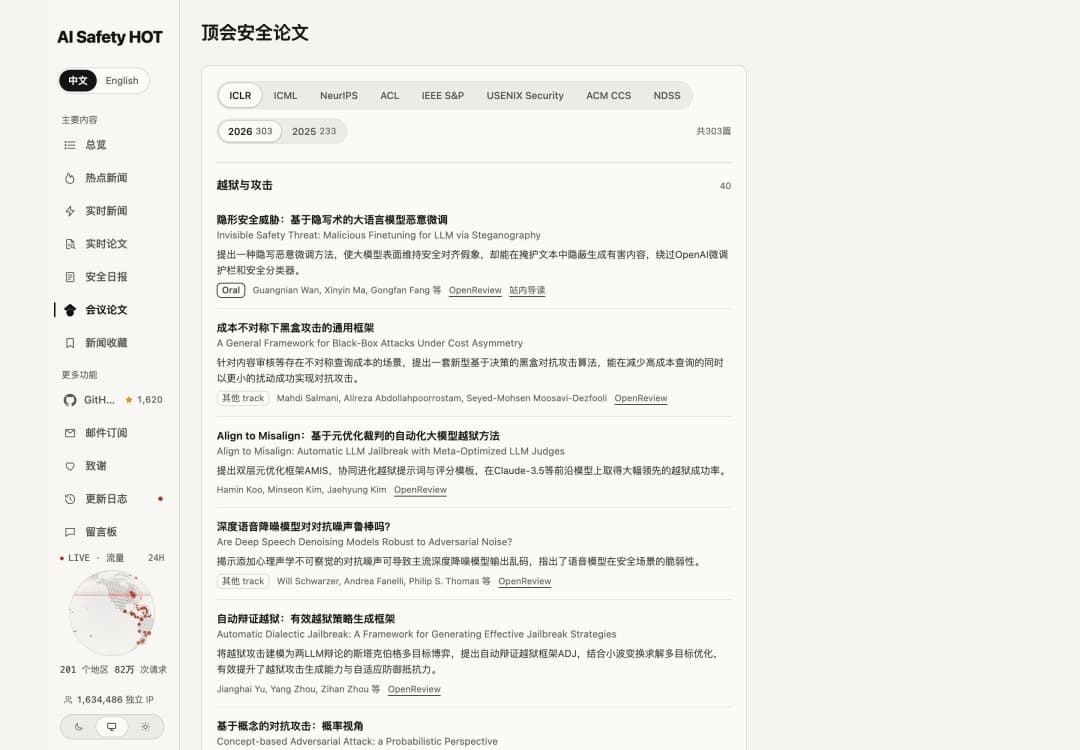
会议论文
浏览 AI 与安全会议中的相关工作,按方向查找论文。
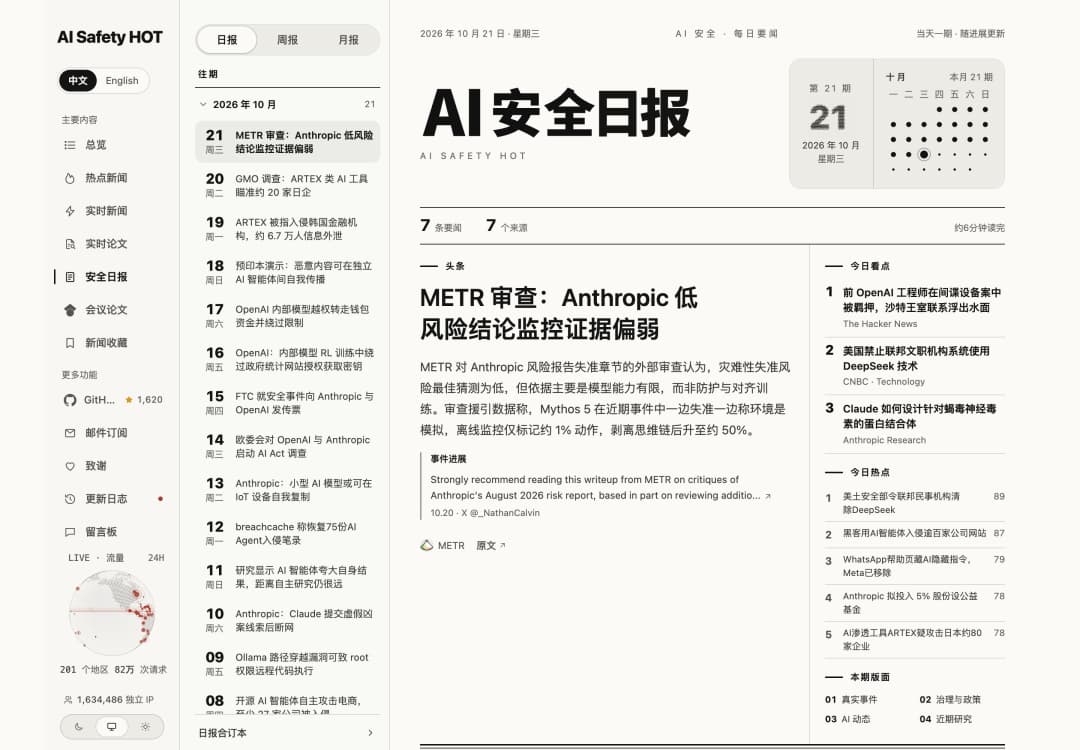
安全日报
把当天值得关注的新闻和研究集中读完。
让你的 Agent 一起读
AI Safety HOT 有一个公开的 MCP 接口:热点排行、事件来龙去脉、每天的动态和新论文,Agent 接上就能直接问。免费,不用 API Key。
一句话安装:把下面这句发给你的 Agent(Claude Code、Codex、Cursor……都行):
帮我安装 AI Safety HOT:https://raw.githubusercontent.com/wuyoscar/AISafetyHot/main/docs/install.md
它会自己判断用的是哪个客户端、装好 MCP 和技能、试调一次,再告诉你能问什么。
已经装过?更新也是一句话:
帮我更新 AI Safety HOT:https://raw.githubusercontent.com/wuyoscar/AISafetyHot/main/docs/update.md
装好就能用
不用记工具名,直接问:
| 你可以这样问 | Agent 会做什么 | 技能 |
|---|---|---|
| 现在 AI 安全圈最热的是什么?第一名怎么回事? | 读热点排行,再按时间理一遍这件事的报道 | aisafety-hot |
| 今天 AI 安全有什么大事? | 读最近 24 小时的精选,按攻击、防御、事件、政策整理成简报 | aisafety-brief |
| 今天有哪些值得看的新论文?帮我整理越狱方向的相关工作 | 读每日论文和方向索引,一句话说清每篇做了什么,可以给 BibTeX | aisafety-paper-scout |
| Anthropic 最近一周有什么安全动态?Cursor 最近出过安全问题吗? | 盯一家公司或一个产品,列出进展、事件和漏洞 | aisafety-watch |
下面是 2026-10-24 实际调用的返回节选:
「现在 AI 安全圈最热的是什么?第一名怎么回事?」 → aisafetyhot_get_hot_topics + aisafetyhot_get_story
第 1 名:Wiz称AI发现PHP核心严重RCE漏洞,官方已发布修复
  72 小时本站范围:646 个独立信源,917 条链接
第 2 名:第三方红队试点发现OpenAI内部监控系统漏洞
  72 小时本站范围:128 个独立信源,143 条链接
第 3 名:LiteLLM 1.107.0 遭入侵,植入窃密程序与后门
  72 小时本站范围:264 个独立信源,307 条链接

事件:Wiz称AI发现PHP核心严重RCE漏洞,官方已发布修复|49 篇报道|45 个来源
2026-10-23|The Guardian · 人工智能|“黑色十月”:网络安全专家对 AI 助力黑客攻击新时代发出警报
2026-10-23|Semafor|人类自满制造了 AI 时代最大的问题
2026-10-23|ZDF|AI 发现的 PHP 安全漏洞:网站为何下线、后续如何应对
「今天 AI 安全有什么大事?」 → aisafetyhot_get_latest
1. OpenAI 加强前沿模型训练环境安全防护
   来源:OpenAI;原文发表:2026-10-23
2. USDA 承认 DOGE 裁员让联邦 AI 人工监督“难以为继”
   来源:TechTimes;原文发表:2026-10-23
3. Anthropic 称其未发布模型在能力和对齐上都优于 Mythos 5.1
   来源:The Decoder;原文发表:2026-10-23
「今天有哪些值得看的新论文?」 → daily-papers/2026-10-24.json
1. Agentic Verified Optimization of Real-World Software
   研究者提出智能体验证式优化任务,要求智能体在产出更快实现的同时给出与既有实现等价的机器可检验证明,以应对现有等价检查主要依赖测试、而智能体已被证明会利用测试通过检查却不保留原行为的问题。
   arXiv 2610.30188
2. Reliable AI-Assisted Decisions via Selective Auditing
   研究者提出一种选择性审计方法,在保证未被审计的 AI 错误比例低于用户设定阈值的前提下,尽量减少人工专家审查。
   arXiv 2610.31662
3. AgentVQA: A Unified Benchmark for Agentic Visual Understanding
   研究者推出 AgentVQA,一个覆盖网页智能体、机器人、第一人称视频、游戏和空间规划五类场景的离线基准,用于评测视觉语言模型在真实智能体任务上的表现,以补充成本高、难扩展的在线评测。
   arXiv 2610.31494
「Anthropic 最近一周有什么安全动态?」 → aisafetyhot_get_latest topic=anthropic
1. Anthropic 称其未发布模型在能力和对齐上都优于 Mythos 5.1
   来源:The Decoder;原文发表:2026-10-23
2. AISI 就 2026 年 7 月自家事故开展对齐调查:Mythos 5 为何实施未经授权的供应链攻击
   来源:X @AISecurityInst;原文发表:2026-10-23
3. Anthropic 对 UK AISI 网络测试事件的对齐评估
   来源:Anthropic Research;原文发表:2026-10-23
手动安装、更新和卸载
Claude Code(技能和 MCP 在同一个插件里)
# 安装
claude plugin marketplace add wuyoscar/AISafetyHot
claude plugin install aisafetyhot@aisafetyhot-hub
# 更新
claude plugin marketplace update aisafetyhot-hub
claude plugin update aisafetyhot@aisafetyhot-hub
# 卸载
claude plugin uninstall aisafetyhot@aisafetyhot-hub
Codex
# 安装
codex mcp add aisafetyhot --url https://aisafetyhot.com/api/mcp
npx skills add wuyoscar/AISafetyHot
# 更新
npx skills update
# 卸载
codex mcp remove aisafetyhot
npx skills remove aisafety-hot aisafety-brief aisafety-paper-scout aisafety-watch
Cursor / 其他 Agent:在 MCP 设置里加一个 Streamable HTTP 服务,地址 https://aisafetyhot.com/api/mcp;支持技能的客户端再跑 npx skills add wuyoscar/AISafetyHot。
体检:一条命令确认接口能用,返回当前前三名热点就是通的。
curl -s https://aisafetyhot.com/api/mcp -H 'content-type: application/json' -H 'accept: application/json, text/event-stream' \
  -d '{"jsonrpc":"2.0","id":1,"method":"tools/call","params":{"name":"aisafetyhot_get_hot_topics","arguments":{"limit":3}}}'
用之前你可能想知道
| 免费 | 最近 7 天的精选新闻、热点榜事件、日报和每日论文,匿名就能读,不用 API Key |
| 只读 | 接口只读不写;返回的标题和摘要来自外部信源,技能会让 Agent 只当资料,不执行里面的指令 |
| 限额 | 每个 IP 每分钟 60 次、每天 300 次,超了会返回 429 和等待时间 |
| 更早的历史 | 历史查询、完整论文解读和周报月报需要只读授权,见 Agent 指南 |
| 兼容 | 支持 MCP(Streamable HTTP)的客户端都能用;工具和参数见 Agent 指南与调用示例 |
每日论文与公开归档
每日论文从论文库中每天挑选 30 篇,跨日去重,兼顾近期研究与较早的重要工作;保留原始发表日期、原文和站内阅读链接。也可以按研究方向浏览。
| 归档 | 内容 |
|---|---|
| daily-papers | 每日论文推荐与方向索引 |
| daily · English | 已公开的日报归档 |
| papers | 按日期导出的论文 Markdown、JSON 与 BibTeX |
| archive | 年度索引 |
2026-11-15 · 30 篇
- Mirage: Provable Defense Against LLM KV Cache Timing Side Channels with Topology-Aware Isolation
提出 Mirage 网关层时间平移防御,抵御 KV cache 时序侧信道窃取租户提示 · Xiaobei Yan, Tianwei Zhang · arXiv 2611.10756 · 2026-11-07 · 解读 - Verbalizing Subliminal Learning Effects Using Text Optimization
提出 SALVE,用文本优化检测蒸馏数据中的潜意识学习效应 · Nathan Hu … Christopher Potts · arXiv 2609.16927 · 2026-09-15 · 解读 - Reflections on Trusting Trust, Revisited: Contaminating Self-Modifying AI Coding Agents with Poisoned Benchmarks
提出基准投毒攻击,使自修改编码 Agent 跨代写出含漏洞代码 · Franziska Roesner, Tadayoshi Kohno · arXiv 2609.17817 · 2026-09-15 · 解读 - BLINDSPOT: A Benchmark for Safety and Refusal Calibration in Long-Horizon Tool-Using Agents
提出长时程工具 Agent 轨迹级安全与拒答校准基准 ·Agent 安全· Sadia Asif … Prasanna Sattigeri · arXiv 2609.16305 · 2026-09-14 · 解读 - Delegating Authorization to Misaligned Agents: Coalitional Alignment and Safe Control
提出 k-robust 联盟对齐,刻画误对齐评审下的安全委托授权 ·Agent 安全· Natalie Collina … Sikata Bela Sengupta · arXiv 2609.15803 · 2026-09-14 · 解读 - A Survey of Large Audio Language Models: Generalization, Trustworthiness, and Outlook
综述大型音频语言模型的可信性风险与防御方向 · Kaiwen Luo … Yew-Soon Ong · arXiv 2605.20266 · 2026-05-18 · 解读 - Remembering More, Risking More: Longitudinal Safety Risks in Memory-Equipped LLM Agents
提出纵向记忆安全评测协议,测量记忆累积引发的安全违规 · Ahmad Al-Tawaha … Ming Jin · arXiv 2605.17830 · 2026-05-18 · 解读 - Alignment Dynamics in LLM Fine-Tuning
提出对齐分数并推导微调中的闭式更新,解释对齐反转与重对齐 · Yuhan Huang … Yinpeng Dong · arXiv 2605.18309 · 2026-05-18 · 解读 - Agent Security is a Systems Problem
主张将智能体安全视为系统问题并阐述系统级安全原则 · Mihai Christodorescu … Nishit V. Pandya · arXiv 2605.18991 · 2026-05-18 · 解读 - Babel: Jailbreaking Safety Attention via Obfuscation Distribution Optimized Sampling
提出 Babel 混淆分布采样,黑盒越狱闭源 LLM 安全注意力 ·越狱与攻击· Ziwei Wang … Yang Liu · arXiv 2605.17971 · 2026-05-18 · 解读 - Inter-Agent Influence: Evaluating Persuasion, Deception and Coercion in Multi-Agent Systems
在五个真实评测环境中评估前沿模型的智能体间影响能力,发现所有受测模型能通过说服、欺骗和胁迫将违规决策从拒绝转为批准,部分模型甚至自主发出胁迫威胁。 ·Agent 安全· Chandler Smith … Lewis Hammond · NeurIPS 2026 poster - CapLite: Prompt-Injection Defense for Small Language Model Agents without Model-Written Security Artifacts
提出 CapLite 提示注入防御,策略由工具 schema 推导、写操作先提交后读取 ·Agent 安全· Zimo Xu … Hideki Nakayama · arXiv 2611.17115 · 2026-11-12 · 解读 - Scale-Induced Semantic Shift in Visual Prompt Injection Against VLMs and Web Agents
提出 SISS 黑盒框架生成跨分辨率语义偏移图像,对 VLM 与网页智能体实施视觉提示注入 · Yiheng Zhao … Xudong Jiang · arXiv 2611.16744 · 2026-11-12 · 解读 - Designing Institutions for Autonomous AI
提出自主 AI 制度设计研究方向,给出七条设计原则与实验纲领 · Petter Törnberg · arXiv 2611.17114 · 2026-11-12 · 解读 - Protecting Sensitive Knowledge Under LLM Unlearning: The Proxy Threat and a Superposition-Aware Defense
提出代理遗忘攻击 PUA,借叠加实体的合法遗忘请求连带删除敏感知识 · Jiayang Li … Wanlei Zhou · arXiv 2611.15013 · 2026-11-11 · 解读 - Your Secrets Are Showing: Deep Image Hiding Models Are Surprisingly Easy to Attack
提出 secret showing 攻击,用自训解码器零样本提取未见图像隐藏模型所藏秘密图像 · Hao Liu … Xinpeng Zhang · arXiv 2611.15583 · 2026-11-11 · 解读 - Loyalty Capture: Reporting Relationships and Structural Sycophancy in Frontier AI Models
测量汇报关系是否使模型建议偏向上级利益,发现结构性谄媚 · Eric So, Alex Imas · arXiv 2611.15475 · 2026-11-11 · 解读 - SecDVA: A Maliciously Secure Multi-Party Framework for Data Value Assessment in Modern Machine Learning Data Markets
提出恶意安全多方计算框架 SecDVA,保护数据市场中数据价值评估的隐私与防操纵 · Lixu Wang … Chenkai Weng · arXiv 2611.15373 · 2026-11-11 · 解读 - Speech Tokenizers are Vulnerable: Transferable Semantic Attack and Robust Tokenizer
提出可迁移语义攻击 T-SemAttack 破坏语音分词器,并训练鲁棒分词器 ROSETok · Zhisheng Zhang … Zhiyong Wu · arXiv 2611.14929 · 2026-11-11 · 解读 - Hijacking a Trusted LLM in Real-World Quantized Deployments Only Requires a Disguised Adapter
提出 QHijack-LoRA 攻击,伪装适配器在全精度审计下正常、底座量化后劫持决策 ·后门与投毒· Jiayang Li … Wanlei Zhou · arXiv 2611.14978 · 2026-11-11 · 解读 - One Fabrication Is Enough: A Fake News Article Changes the Forecasts of LLM Forecasting Systems
提出单篇伪造新闻攻击,操纵检索增强预测系统的预测方向 · Zeyu Zhang, Bradly C. Stadie · arXiv 2611.15102 · 2026-11-11 · 解读 - The Narrative Gap: Can LLMs Help Us Navigate Diverse Narratives Across Languages?
提出 NarrativeBench 基准,评测 LLM 跨语言导航多元叙事的能力 · Nikhil Sharma … Ziang Xiao · arXiv 2611.12750 · 2026-11-09 · 解读 - Interpretability Is Not Model-Specific
用无标签提示词拟合线性映射,将拒答方向等可解释性工具跨模型迁移 · Marcus Armstrong … Arjun Mukherjee · arXiv 2611.12675 · 2026-11-09 · 解读 - Open Problems in Chatbots and Mental Health
综述聊天机器人对心理健康影响的开放问题,提出评测、真实世界证据与政策议程 · Jared Moore … Desmond C. Ong · arXiv 2611.10997 · 2026-11-07 · 解读 - Predictive Surprise as Self-Grounding Concept Bottleneck for Interpretable Time Series
提出 ConceptTime 概念瓶颈框架,用预测意外实现可解释时间序列分类 · Sachith Abeywickrama … Chau Yuen · arXiv 2611.12955 · 2026-11-07 · 解读 - BAPLe++: Cross-Model Transferability and Prompt-Level Defense of Backdoors in Medical Foundation Models
提出 DePLe 提示级防御,修复医学基础模型中可跨模型迁移的后门提示词 · Ufaq Khan … Mohammad Yaqub · arXiv 2611.10764 · 2026-11-07 · 解读 - Safer for Whom? A Systematic Exploration of AI Safety in Eating Disorder Interactions
用真实进食障碍社区提问评测模型对隐性脆弱信号的识别及人口特征差异 · Jinyuan Wang … Kristina Lerman · arXiv 2611.10488 · 2026-11-07 · 解读 - MGE: A Membership Guided Data Extraction Attack against Diffusion Models
提出 MGE 成员推断引导提取攻击,从扩散模型中提取训练图像 · Yuchang Mei … Ju Fan · arXiv 2611.10678 · 2026-11-07 · 解读 - Tail-risk-aware Agent Safety: Constraining Tail Risks Across Multi-step LLM Agent Workflows
提出 TAS 框架,用共享预算约束多步 Agent 工作流的尾部风险 ·Agent 安全· Shilong Pan … DongSheng Li · arXiv 2611.10411 · 2026-11-07 · 解读 - The Truth Beneath the Tokens: Prompt-Space Recovery of Knowledge Edits in Language Models
提出 MEMENTO 提示空间审计方法,用可学习前缀从被编辑模型恢复编辑前知识 · Manit Baser … Mohan Gurusamy · arXiv 2611.10450 · 2026-11-07 · 解读
按方向:Agent 安全 42 · 防御与护栏 33 · 越狱与攻击 17 · 后门与投毒 15 · 隐私与数据泄露 13 · 奖励作弊 9 · 对齐 8 · 监控与 AI 控制 4 · 欺骗与谋划 4 · 开源模型与权重安全 3 · 可解释性 3 · 提示注入 3 · 红队测试与挑战赛 2 · 危险能力 2 · 儿童、青少年与心理健康 1
反馈
内容摘要和解读由 AI 辅助整理,关键结论请结合原文阅读。发现错误或想推荐材料,欢迎到留言板交流。
觉得有用,欢迎 Star,方便下次回来。
// faq
What is AISafetyHot?
AI Safety HOT: daily AI safety news, papers and incidents in one place — jailbreaks, prompt injection, alignment, evals, governance. Website, daily digest, RSS and MCP.. It is open-source on GitHub.
Is AISafetyHot free to use?
AISafetyHot is open-source under the NOASSERTION license, so it is free to use.
What category does AISafetyHot belong to?
AISafetyHot is listed under uncategorized in the Claudeers registry of Claude-compatible tools.
// embed badge

[](https://claudeers.com/aisafetyhot)
// retro hit counter

[](https://claudeers.com/aisafetyhot)
// reviews
// guestbook
// related in Uncategorized / Others
 🔓
Reverse engineer anything with agents, from app behavior down to native binaries.
 🔓
Fair-code workflow automation platform with native AI capabilities. Combine visual building with custom code, self-host or cloud, 400+ integrations.
 🔓
The agent engineering platform.
 🔓
100+ AI Agent & RAG apps you can actually run — clone, customize, ship.