
roam-code
Local codebase intelligence CLI + MCP server for AI coding agents: SQLite code graph, 28 languages, 287 commands, 246 MCP tools, change-safety gates, audit e…
Install with your AI
Paste into Claude Code, Cursor, or any agent — it reads the repo and wires the tool into your project.
Install and set up roam-code (claude-plugin project) into my current project.
Found on https://claudeers.com/roam-code
Repo: https://github.com/Cranot/roam-code
Homepage/docs: https://roam-code.com/
Detected install method: claude-plugin → /plugin install roam-code@Cranot/roam-code
Category: mcp-servers. Platforms: cli, api, desktop, web, mobile.
Read the repo's README for exact setup and env vars, then install it and wire it into my project.

Claudeers Health Verdict:
active; community-verified: false. Confirm the source before running anything.
/plugin marketplace add Cranot/roam-code
/plugin install roam-code@Cranot/roam-code
git clone https://github.com/Cranot/roam-code
// compatibility
| Platforms | cli, api, desktop, web, mobile |
|---|---|
| Operating systems | — |
| AI compatibility | claude |
| License | Apache-2.0 |
| Pricing | open-source |
| Language | Python |
roam-code
Understand your codebase. See what a change might affect. Give your coding agent better context.
Runs on your machine · no account or API key for local analysis · no automatic source-code or telemetry upload · free and open source
287 commands · 246 MCP tools (17 in the default core preset) · 28 languages
Jump to — Why Roam · Install · Context for your agent · Core commands · MCP server · AI-tool integration · Roam Guard (PR gate) · Performance · Compare · Pricing · FAQ
Why Roam is different
Roam helps you find your way around a repository before you change it. It builds a local map of functions, classes, imports, and the connections between them, then uses that map to answer questions like:
- Where does this feature start, and which files should I read?
- Who calls this function? What else could my change affect?
- Which tests are connected to this code?
- What did we actually check before calling this change ready?
Use it yourself in the terminal, or let your coding agent query it through the CLI or MCP (a standard way for assistants to use tools). You do not need to learn hundreds of commands: start with the five below.
Roam complements your editor, text search, tests, and code review. Its useful difference is the connections: a search finds a name; Roam helps you follow where that name is defined and used. Those connections come from static analysis, so they can be incomplete. A suggested test list is not test coverage, and a good health score is not permission to merge.
Local analysis needs no account or API key. It does not automatically upload your code, index, findings, or telemetry. Installation and the first parser download need network access; optional online features have explicit triggers. See what can contact the network before using Roam in a restricted environment.
For teams that need a review record, Roam can save what changed, which checks ran, and why a gate passed or stopped. Signed records can reveal later changes to the evidence; they cannot prove that every relevant check was captured. Read what verification evidence does and does not prove.
Install + first four commands
Start in a Git repository you want to explore:
pip install "roam-code[mcp]"          # 1. install the CLI and optional agent-tool server
cd /path/to/your/repo
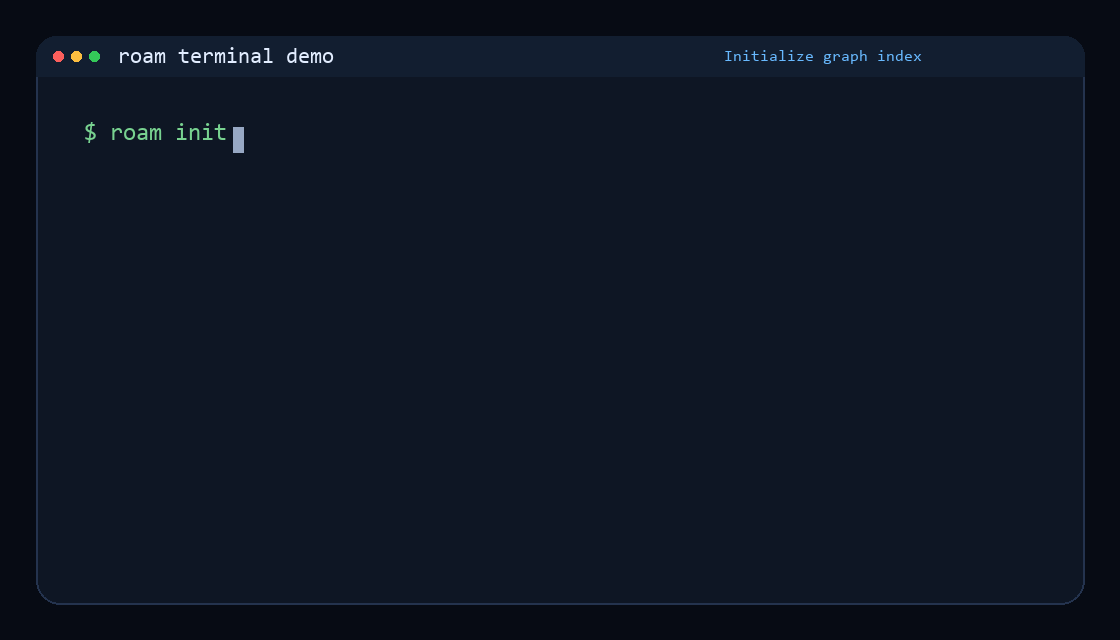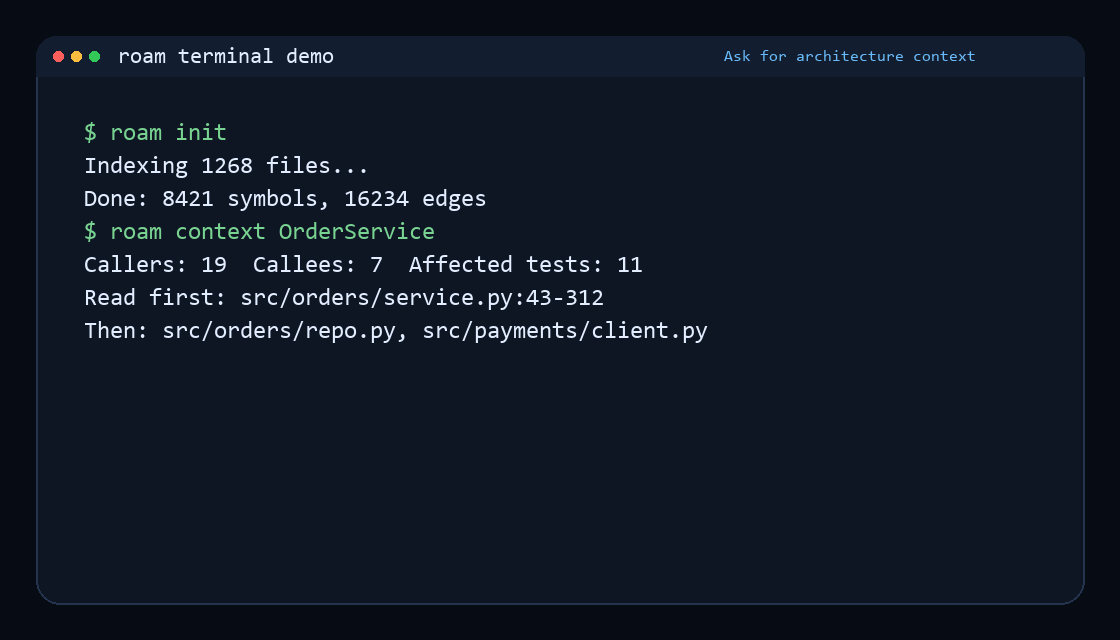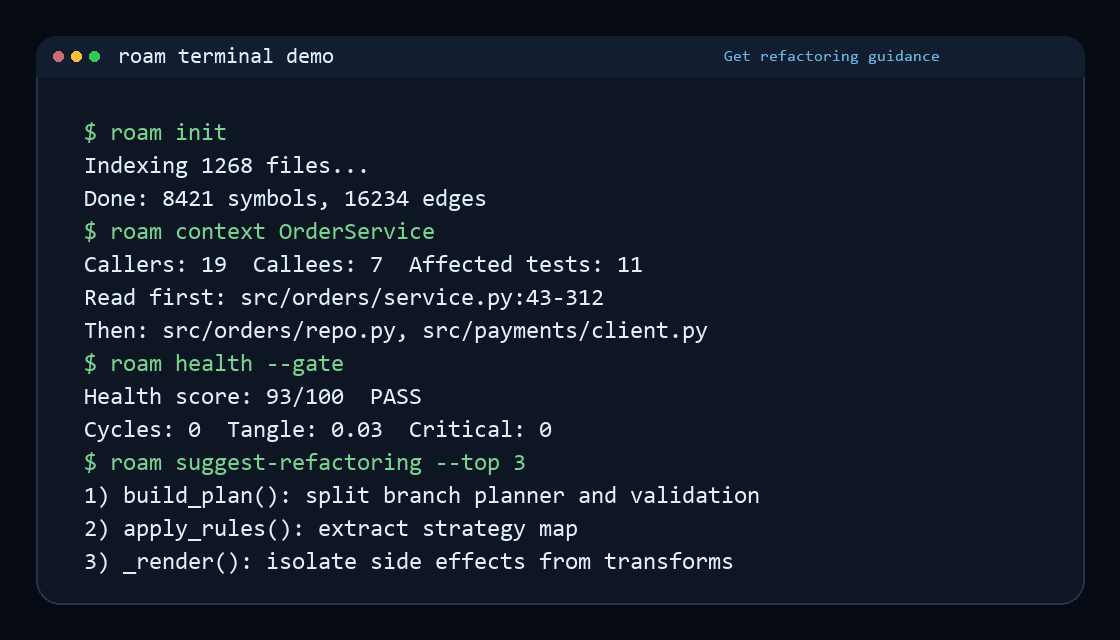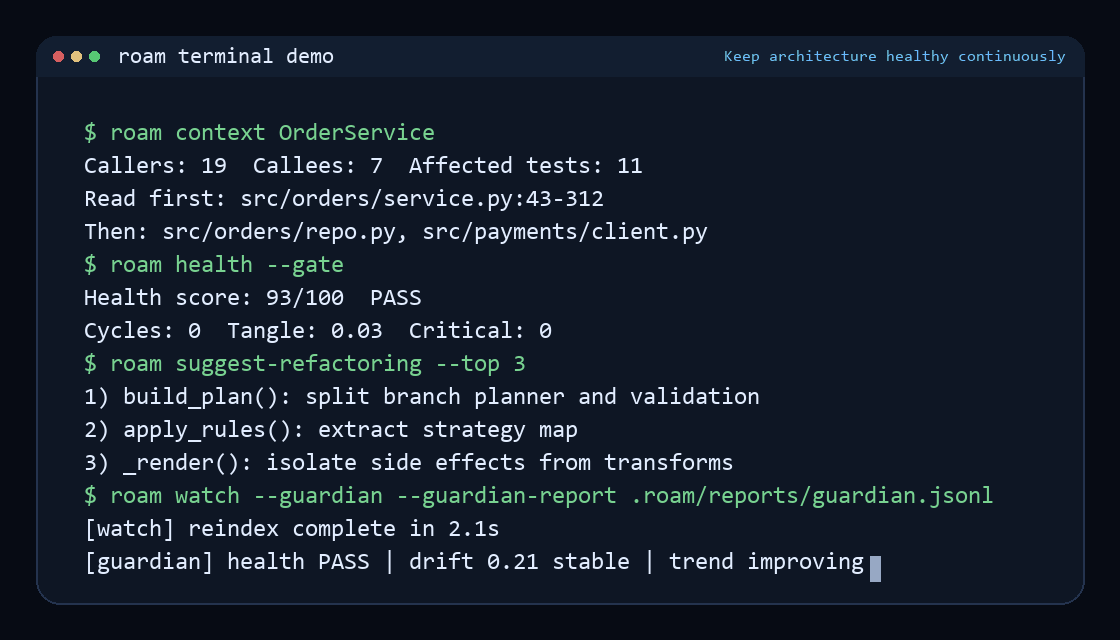
roam init                            # 2. build the local index and project configuration
roam health                          # 3. see a summary of code structure and findings
roam preflight <symbol>              # 4. check a function or class before changing it
Python 3.10+. pipx install roam-code and uv tool install roam-code work too. Drop [mcp] for CLI-only. See docs/fresh-install-smoke.md for a verbatim transcript of these four commands against a clean venv.
Replace <symbol> with a function or class from your project. To find one,
run roam search <name>. The first index takes longer than later refreshes;
timing depends on repository size and your machine. Use roam index instead
of init if you only want the index, without creating project configuration.
Here is a recorded example from Roam's own codebase. open_db is used widely,
so the report calls out the size of the change before you make it. The counts
below are a snapshot, not live measurements of your checkout:
$ roam preflight open_db
VERDICT: Significant risk — CRITICAL, 17922 symbols in blast radius

Pre-flight check for `open_db (src/roam/db/connection.py:1076)`:

  Blast radius:     17922 symbols in 1732 files              [CRITICAL]
  Affected tests:   681 direct, 14126 transitive             [OK]
  Complexity:       cc=5, nest=2                             [LOW]
  Coupling:         2 files often change together            [MEDIUM]
  Conventions:      no violations                            [OK]
  Fitness:          target passes; 1 rule(s) fail on sibling symbols [OK]

  Overall risk: CRITICAL
  Risk driver:  blast radius (17922 symbols in 1732 files, CRITICAL)
“Blast radius” means code that could be affected through the indexed connections; it does not mean all of those functions will break.
Alternate install methods + Docker
pipx install roam-code                                   # isolated environment (recommended)
uv tool install roam-code                                # uv-managed tool
pip install git+https://github.com/Cranot/roam-code.git  # from source

# Docker (local build; CLI + MCP dependencies)
docker build -t roam-code .
docker run --rm --user "$(id -u):$(id -g)" -e HOME=/tmp -v "$PWD:/workspace" roam-code index
docker run --rm --user "$(id -u):$(id -g)" -e HOME=/tmp -v "$PWD:/workspace" roam-code health
Works on Linux, macOS, and Windows. Windows: if roam is not found after installing with uv, run uv tool update-shell and restart your terminal.
Context for your agent
When you ask an agent “who calls handleSave?”, it often starts by searching
and opening files. Roam's task compiler can do some of that preparation
locally and attach relevant context to the prompt: callers with line numbers,
recent changes, or the source around a reported bug. It makes no model calls
of its own. Your agent still needs to assess the context and do the work.
For Claude Code, install the hooks once from the project directory:
pip install "roam-code[mcp]"
cd your-repo && roam init
roam hooks claude --write     # compile-before + verify-after, wired into Claude Code
Then use claude exactly as you always do. Undo anytime with
roam hooks claude --uninstall --write. Compile-time context injection is
fail-open. After an edited turn, the Stop gate is deliberately fail-closed:
findings, malformed output, an unavailable check, or incomplete evidence must
be resolved before Claude reports completion. No-edit Q&A turns fast-exit.
Historical tests found fewer agent turns and lower costs for some tasks, with regressions on others. These are dated experiments, not a promise about your model or repository. The full results and limitations remain below.
Benchmark results and history (May–July 2026)
What was measured head-to-head on Claude (same prompts, same repo, with and without the compiler — June 2026, 41 cells):
| Median per task | vanilla | compiled | delta |
|---|---|---|---|
| Agent turns (navigation/comprehension) | 6 | 1 | −83% |
| Input tokens | 271K | 53K | −80% |
| Cost | $1.30 | $0.48 | −63% |
| Wall time | — | — | −50% |
A second run on Opus shows the same direction at smaller magnitude (−33% turns overall; the best single cell hit −88%). And the compiler knows where it doesn't help: prompts that ask the agent to write code get no envelope at all — injection there was measured as pure overhead, so it spends your tokens only where it wins.
The full data — every bench cell (including the losses), the ground-truth bug bench, and routing stats
| Task | turns | input tokens | cost |
|---|---|---|---|
"where is open_db defined?" | 3 → 1 | 156K → 51K | $0.67 → $0.28 |
"which files depend on cli.py?" | 6 → 1 | 252K → 51K | $1.15 → $0.30 |
| "where is the env var configured?" | 9 → 1 | 497K → 53K | $1.40 → $0.31 |
| "what are the layers of this codebase?" | 5 → 1 | 271K → 50K | $1.42 → $0.41 |
"what changed in cli.py recently?" | 4 → 2 | 186K → 104K | $0.62 → $0.40 |
| "explain the compiler module's architecture" | 13 → 6 | 618K → 240K | $1.85 → $1.01 |
| "trace how a command becomes an MCP tool" | 12 → 8 | 464K → 303K | $1.25 → $1.01 |
| security-hook comprehension (hard, multi-file) | 6 → 2 | 267K → 117K | $1.15 → $0.56 |
| "what are the biggest cycles in this codebase?" (re-measured 06-11) | 6 → 1 | — | $0.65 → $0.07 |
| "where is the CLI entry point?" (trivial, re-measured 06-11) | 1 → 1 | 48K → 50K | $0.21 → $0.22 |
| "write a pytest for X" (generation, re-measured 06-11) | 5 → 7 | 275K → 396K | $0.61 → $0.45 |
The last two rows were the published LOSSES (trivial prompts once paid the envelope for nothing at +$0.20; generation once cost +17%). After the generation-skip lever (write-code prompts get a ~0.6 KB lean envelope or none — measured 3.5% of a 723-prompt real corpus) and the entry-point routing fix, both cells were re-measured at n=3 medians on the same model: generation flipped to a −26% cost / −18% wall win — input tokens rise (cache-read-heavy, cheap) while expensive output tokens drop −29% across more-but-cheaper turns — and the trivial cell is a tie within noise. Losses are findable because we publish them — and fixable because the compiler routes them.
Bug-fixing, ground-truth graded (a failing test must transition to passing — no LLM judging): 20 cells of planted bugs with real tracebacks — 10/10 fixed in both arms at −13% dollar cost. Read that honestly: n=10 cannot establish quality parity (the 95% interval on 10/10 spans [72%, 100%]), and the dollar saving comes with more tokens, not fewer on this task class — the envelope shifts spend into cheaper cache reads. No quality difference was detected; the sample has little power to detect one.
Routing, replayed on 723 real prompts from live agent sessions: 57% of envelopes ship pre-executed answers (L1 probes) — the envelope already contains the literal answer — and a further ~33% ship structured facts (context, not the literal answer), at p50 0.45 s cold / p50 92 ms live (warm cache) compile latency, fully local. Zero model calls.
Eval history by version — losses are published, attacked, then re-measured. The ledger is not re-run on every release: the newest measured kernel is v13.7 (Jul 11), and later kernel releases have shipped since without a fresh A/B. Read every row below as measured-at-the-stated-kernel, not as a current-release claim. The table is the summary ledger; raw per-cell data for the historical runs is retained privately, not in this repository:
| measured | kernel | what | result |
|---|---|---|---|
| Jun 09 | v13.4 | 41-cell nav/comprehension A/B | turns −83%, tokens −80%, cost −63% |
| Jun 09 | v13.4 | 20-cell ground-truth bugbench | 10/10 both arms (n=10 — no parity claim), $ −13% but tokens up |
| Jun 09 | v13.4 | trivial-prompt cell | +80% cost — published loss |
| Jun 09 | v13.4 | generation cell | +17% cost — published loss |
| Jun 11 | v13.6 | trivial-prompt cell, re-measured n=3 | tie ($0.21 → $0.22) |
| Jun 11 | v13.6 | generation cell, re-measured n=3 | −26% cost win |
| Jun 11 | v13.6 | "biggest cycles" cell, re-measured n=3 | −89% cost win ($0.65 → $0.07, 6→1 turns) |
| Jun 11 | v13.6 | 723-prompt routing replay | 57% L1 (answer-shipping) + ~33% facts, p50 0.45 s cold |
| Jul 11 | v13.7 | live dogfood rolling window (separate population, not the replay harness) | cold-compile median 410 ms |
Caveats that always ship with these numbers: trivial prompts the agent one-shots anyway gain nothing (now a within-noise tie after the lean/skip levers); cells are n=2–3 with medians and ranges.
Benchmark archaeology — runs #1–#4 (May 2026), including the honest negative result that drove the fixes
Two independent A/B runs at different scales — the larger sample inverts the smaller. Reporting both honestly.
Run #1 (n=3 per cell, 27 cells, $16.88): compile appeared to dominate (−29% wall vs static). That static prompt included a "Hard cap: 4 tool calls" line that turned out to act as a quota.
Run #2 (n=3–7 per cell, 78 cells, $54.88, "Hard cap" line removed from static):
| Condition | Mean turns | Mean wall | Mean cost |
|---|---|---|---|
| vanilla | 7.0 | 33.2s | $0.68 |
| static / roam_agent | 5.8 | 25.1s | $0.66 |
| compile | 8.2 | 47.9s | $0.78 |
At scale, static (with the "Hard cap" line removed) is the winner: −17% turns and −24% wall vs vanilla, with cost within 3%. The compile-mode envelope was +91% wall vs static on hard structural tasks — variance probe revealed compile occasionally pushes the agent into over-tool-use (one t1 run hit 41 turns and $2.43). The compile-the-COMMAND itself is robust (250/250 latency cells, 14/15 fuzz, brief mode <300 chars across all 10 procedure families) — the issue is over-direction of the consuming agent, not the compiler.
Private raw cells are retained for audit; the public summary above is the quotable result.
Run #3 (2026-05-31, n=1, 24 cells, $12.78, on 8-task user-shape corpus after W34→W37 fixes):
| Condition | Mean turns | Mean wall | Mean cost |
|---|---|---|---|
| vanilla | 6.00 | 28.6s | $0.58 (1 cell timed out at 240s) |
| static / roam_agent | 5.38 | 39.9s | $0.63 |
| compile | 2.75 | 35.6s | $0.46 |
This run inverts Run #2 on a different corpus. Compile wins 7/8 shapes including stack-trace, "what does X do", "what changed recently", compare files, who calls X, file coupling, and trace-flow. The compiler fix wave between Run #2 and Run #3 added six new probes (stack-trace source slice, body-embed for explain, git-log for history, sibling-test embed, path-comparison diff, symbol-pickaxe) and four real bug fixes (callers-backtick fallback, dead-code wrong CLI, consumer-dict flattening, stack-trace classifier missing PascalCase Errors). Headline win: a "what files are coupled to X" task that took vanilla 20 turns / $1.20 / 64s collapsed to compile's 1 turn / $0.32 / 11s — embedded coupling pairs eliminate 19 turns of exploration. The +24% wall vs vanilla is the envelope cache-creation tax at n=1; expected to amortize at n≥3.
Static remains a non-improvement (0/8 wins vs vanilla, 1/8 marginal vs compile). Caveat: Run #3 is n=1 per cell; n=3 replication ($30-40) is pending.
Private per-task tables and raw cells are retained for audit; the public summary above is the quotable result.
Run #4 (2026-05-31, n=1, 24 cells, $13.00, same corpus after W43→W45 polish/improvements/corrections):
| Condition | Mean turns | Mean wall | Mean cost |
|---|---|---|---|
| vanilla | 5.25 | 39.6s | $0.63 |
| static / roam_agent | 4.75 | 32.8s | $0.61 |
| compile | 1.88 | 25.2s | $0.40 |
Compile now wins 8/8 shapes and the +24% wall penalty from Run #3 is gone: compile is −36% wall vs vanilla. Aggregate −64% turns / −36% cost / −36% wall vs vanilla on Opus 4.7. The flip came from three wave-43-to-45 changes: (a) a 60-second bounded cache on _run_roam subprocess calls, (b) anti-Read directives in the stack_trace_fix and synthesis_query answer contracts, and (c) richer enrichment in the write_pytest probe (sibling test + source under test + nearest conftest.py together). The biggest single delta: write_pytest went from 10 vanilla turns to 6 compile turns (−40%, saving $0.29 / cell). Static remains 0/8 wins and should be retired from the default bench-compile conditions in a future release.
Private per-task tables and raw cells are retained for audit; the public summary above is the quotable result.
For scripts and CI: roam compile "<task>" --artifact auto.
Prefer a dedicated product CLI? compile-code wraps the same context-and-verification loop and installs roam-code as a dependency. See that repository for installation and its supported workflow.
Check the work after an edit
roam verify --auto chooses checks for the files that changed. Depending on
the change, these include:
- naming — against the codebase's own per-language convention (sampled
from production code only: test/vendored/generated files neither vote nor
get flagged, framework lifecycle names like
setUpare never touched) - imports — check that imports resolve to the index, the stdlib, or a declared dependency. A module path that resolves to nothing fails as a likely hallucination; near-miss names get fuzzy did-you-mean candidates
- error handling / syntax / complexity / cycles / duplicates — scoped structural review with honest disclosure when any sub-check could not run
- secrets — a leak gate over every touched file: credential shapes
(cloud keys, tokens, PEM blocks) fail the check, and an optional
repo-local
.roam-leak-patterns.pycatalogue catches the strings your project must never publish - patterns (advisory,
--deep) — the algorithm/idiom catalog scoped to the diff: N+1 query shapes, loop-invariant calls, string-concat loops, each with the better approach and a fix sketch
The fix loop. Wired via roam hooks claude --write, findings come back
to the agent as an actionable list — fix, then re-verify — and the gate runs
again on each correction (Claude bounds consecutive continuations). A
human-reviewed exception can be recorded in .roam-suppressions.yml, keyed by
symbol so it survives refactors that shift line numbers; automatic hook
corrections cannot alter suppressions, policy, baselines, or verification
scope. The compile hook remains fail-open. The edited-turn Stop gate is quiet
only on a complete PASS and blocks when verification is unavailable,
malformed, incomplete, or reports non-advisory findings.
To focus on your current change or manage findings already in the project:
roam verify --auto                      # changed files, auto-selected checks
roam verify --diff-only                 # only lines you changed vs HEAD
roam verify --changed-lines cli.py:40-90   # exact ranges (agent harnesses)
roam verify --baseline-write            # snapshot current findings as accepted debt
roam verify --new-only                  # then: only NEW findings fail
roam verify --report --severity fail    # whole-repo ranked punch-list (non-gating)
roam verify --off / --on               # pause / resume the loop repo-wide
The commands that run beside it in the same post-edit stance:
| Command | Role in the loop |
|---|---|
roam verify-imports --path src/roam/cli.py | Check import resolution in one file |
roam delete-check --ci | Gates a deletion diff on surviving references (exit 5 on BREAK-RISK or an incomplete check) |
git diff | roam critique | Clones-not-edited check + blast radius on the patch (exit 5 on high severity) |
roam verify --report --persist | Writes findings to the registry so the compiler embeds them as known_findings in future envelopes — debt gets fixed opportunistically |
The test suite includes deliberately broken examples, clean examples that should not be flagged, and checks that saved exceptions survive refactoring. Those tests help prevent regressions; they do not measure every detector's accuracy on unfamiliar repositories. Detector evidence and limitations explains where findings still need careful review.
What's New
v14.0.4 (2026-09-05) — the proof schema now travels with your installation. The JSON Schema used to check proof-bundle structure is included in both package formats, not just the source checkout. Installed-package tests now exercise its public loader, and a new packaging guard catches undeclared data files. Full notes: CHANGELOG.md.
v14.0.3 (2026-09-05) — clearer guidance and more trustworthy check results. Saved proof files keep their review results when read back. Malformed evidence and failed collection cannot turn into a passing result. Benchmark reports keep missing measurements unknown and count failed attempts. The README and verification guide now explain how to get useful answers—and where tests and human review still matter. Full notes: CHANGELOG.md.
v14.0.2 (2026-09-05) — controlled cold starts and more precise loop advice. Keep index control files with a redirected database, opt out of implicit indexing, and receive parseable JSON even on cold starts. Workspace import checks recognize shared development tools without hiding undeclared sibling dependencies. Loop advice accounts for collection mutation, positional lookups, clocks and randomness; complexity-hint matching avoids unrelated AST work. The pinned wheel build tool also receives its path-traversal fix. Full notes: CHANGELOG.md.
v14.0.1 (2026-09-05) — more precise findings and clearer verification. Browser and TypeScript checks distinguish lifecycle calls from database operations, resolve NodeNext source extensions, and show stronger evidence for algorithm advice. Incomplete searches require review instead of authorizing deletion. MCP compatibility is tested against the supported SDK generation, retrieval benchmarks name their dependency profiles, and release checks enforce their stated worker budget. Official container publication remains on hold pending image-wide security review. Full notes: CHANGELOG.md.
Earlier release notes — v13.10
v13.10 (2026-07-28) — repeated work becomes measurable procedures, and post-edit verification becomes proof-complete. Privacy-preserving transcript/shell-template mining can nominate repeated-work interventions without exposing raw prompts or claiming causal savings; roam savings promotes only prospectively joined, integrity-checked outcomes. The Claude adapter now binds every edited turn to a strict Verify receipt and blocks unavailable, malformed, incomplete, or failing evidence. Interrupted indexes carry a generation-bound, durably synced lifecycle marker and force a full non-light rebuild before analysis regardless of the direct caller; completion is published only after SQLite checkpoint/fsync, so a crash cannot turn partial graph state into plausible empty answers. Roam owns the canonical hooks end to end—Compile Code no longer rewrites installed source. Full notes: CHANGELOG.md.
Earlier release notes — v13.6 → v13.0
v13.6 (2026-06-11) — The verify loop grows teeth + compiler injection economics. The post-edit loop now runs a secrets leak gate by default (credential shapes + an optional repo-local .roam-leak-patterns.py catalogue) and an advisory algorithm/idiom sweep scoped to the diff; suppressions are symbol-keyed (refactor-proof) and the suppression file is append-only after a confirmed data-loss fix; the naming rule samples production code only (~2000 false positives removed on a test-heavy codebase) and verify --auto is 16× faster on sweeping diffs. The compiler learns injection economics — generation-shaped prompts get no envelope (measured pure overhead) — plus graph-ranked retrieval (PageRank + file-role + path-token blend), new answer probes (taint scan, world-model idempotency/side-effects, design patterns, scoped algo findings, and verify findings riding into envelopes as known_findings), and routing waves for trace/entry-point phrasings. New offline lock suites (procedure-registry lint, suppression fuzz corpus, self-dogfood FP lock, envelope byte budgets, L1-rate floor) and a prepush_check.py --release gate that proves the full CI surface green before any release push. Full diff in CHANGELOG.md.
v13.5 (2026-06-10) — Compiler coverage waves + the Claude Code adapter. Eight new compile intent procedures land from production-telemetry mining (file_history "what changed in X last week", repo_structure layers/clusters/health, entry_point_where with the authoritative [project.scripts] answer, config_where env-var lookup, module-name describe_file recall, session_meta, a zero-probe fast-path for self-contained batch prompts, and a bug_site_slice that embeds the source around "fix the bug in cli.py:45"); roam hooks claude --write wires the full compile-before/verify-after loop into Claude Code in one command (fail-open, idempotent, --no-verify / --uninstall); two reliability fixes seal a CliRunner stdout-swap race in the in-process probe pool and add a compiler fingerprint to all three compile cache keys; envelope-diff regression rules stop false-flagging budget bookkeeping keys. Compiler A/B on Claude (Fable 5): −83% turns / −80% input tokens / −63% cost on nav-comprehension (41 cells). Full diff in CHANGELOG.md.
v13.4 (released 2026-05-21) — Perf wave + Pattern-1 stabilisation + assurance hardening. Major detector speed-ups (clones 43.8s → 13.1s, intent 66s → 12s, doc-staleness 93s → 19s, sbom 30s → 9s — all byte-identical output), 17 commands now emit isError/status on error envelopes + 11 commands route their argless --json path through a proper envelope (Pattern-1C drift-guards added), a persisted per-snapshot spectral gap powering a real roam forecast failure budget, MCP prompt-injection marker scan on tool-call egress, release supply-chain hardening (PEP 740 attestations, tag-bound artifacts), and large false-positive cuts in feature-envy / shotgun-surgery / god-components. Full diff in CHANGELOG.md.
v13.3 (released 2026-05-19) — MCP runtime security + UX polish
- Egress secret-redaction at the MCP wrapper boundary, 4-mode
policy_decisionenforcement with shadow-mode (ROAM_MODE_DRY_RUN), HMAC-linkedMcpDecisionReceipt+receipt_integrityverdict onroam runs verify. - 3 new persisting detectors (
boundary,test-hermeticity,compatibility),roam doctoradvisory-vs-blocking split, and--jsonwarnings-channel discipline.
v13.2 (released 2026-05-16) — Evidence freshness + resolution disclosure
- Canonical unresolved-path envelopes across
impact/preflight/trace/test-map/context/safe-delete/split/why— one explicit "not found" shape in JSON mode. - Evidence freshness stamped at the producer. Runs record hashes for
.roam-rules.yml,.roam/constitution.yml,.roam/control-map.yml. - PR Replay evidence coverage improved. Replay path maps the 8 evidence questions, fully answers structural change/risk/policy axes, and marks identity/authority/approval evidence as partial, out of scope, or
producer_not_availableinstead of silently omitted.
v13.1 (released 2026-05-15) — Pattern-2 propagation + shared YAML helper + 3 flagship silent-fallback seals
- 3 flagship silent-fallback seals.
cmd_taint,cmd_health,cmd_doctornow emitstate="empty_corpus"+partial_success=Trueon unanalyzed repos instead of falseHealthy 100/100/No taint findings/all checks passedverdicts. - Shared YAML config-loader helper (
load_yaml_with_warnings). 5 of 7 surveyed loaders migrated; ~125 LOC removed. - 5 new live smell detectors.
type-switch,speculative-generality,empty-catch,cross-layer-clone,parallel-hierarchy—roam smellsnow ships 24 deterministic detectors. - 30+ behavioral Pattern-2 fixes + empty-corpus smoke sweep across 25+ detectors.
v13.0 (released 2026-05-13) — Agent-OS substrate + Laravel idioms + Vue SFC
- Agent-OS control plane. Repo-local substrates under
.roam/: constitution, HMAC-chained run ledger, multi-agent leases, portable agent memory, 4 cumulative modes (read_only→safe_edit→migration→autonomous_pr). - World-model classifiers (R28).
roam side-effects,roam idempotency,roam causal-graph,roam tx-boundaries. - Laravel dynamic-dispatch idioms. 7 of 8 implicit-edge idioms (Route closures, Eloquent scopes, Policy resolution, Observer registration, Job/Queue/Artisan dispatch).
- Vue SFC import graph.
.vuetemplate/script/style blocks parsed; component registrations resolved across the SFC boundary. - ~20 new CLI commands (
brief,next,mode,constitution,laws,memory,lease,runs,replay,agent-score,agents-md, …) and schema bump (USER_VERSION 12 → 13).
Full release notes in CHANGELOG.md.
Best for
- Getting oriented — find entry points, important modules, and code worth reading first.
- Working with a coding agent — give it focused context instead of asking it to rediscover everything.
- Planning a refactor — inspect callers, dependencies, and related tests before editing.
- Reviewing changes — collect findings and record which checks actually ran.
- Maintaining a growing project — spot dependency cycles, frequently changed code, and repeated work.
- Investigating security or performance concerns — use findings as leads, then verify them with the right tests and specialist tools.
When NOT to use Roam
- Real-time type checking — use an LSP (pyright, gopls, tsserver). Roam is static and offline.
- Small scripts (<10 files) — read the files directly.
- Pure text search — ripgrep is faster for raw string matching.
What's measured vs advisory
Roam's surfaces differ in how rigorously they've been validated — know which is which before you gate on them:
-
Repair-intent retrieval (
roam retrieve --repair-intent <patch>) — the one surface with a preregistered, held-out, stranger-repo result. Give it the diff of a fix you just made and it reranks toward the other files that need the same repair, rather than the files that merely look similar. Measured on 576 real multi-site fixes from 12 third-party repos (rich, aiohttp, httpx, fastapi, click, flask, jinja, werkzeug, pydantic, pytest, attrs, urllib3), frozen before scoring and shipped in-repo:vs plain lexical search delta 95% CI (bootstrap, n=2000) nDCG@10 +0.064 (0.605 vs 0.541) [+0.032, +0.097] P@3 +0.041 [+0.024, +0.058] MRR +0.059 [+0.026, +0.092] recall@10 +0.034 [−0.002, +0.070] — not significant That clears the preregistered bar (nDCG@10 ≥ +0.05 with a CI excluding zero) and it survived an adversarial falsifier. Read it for what it is: a real but modest improvement over lexical search on this task — not a step change. The one striking result underneath: our graph-sibling candidate pool on its own scores 0.258, far worse than lexical's 0.541. It only beats lexical once repair-intent reranking is applied. The reranking is not polish on a good pool — it is the reason the pool is usable at all.
Scope honestly: it needs a real patch as input, and it finds repair siblings. It is not a general-purpose search improvement, and recall is not measurably better. This is the only roam surface we would put in front of your codebase without hedging.
-
Reachability triage (
roam vuln-reach,roam sbom) — the most conservatively designed surface: reachability is derived only from import evidence (import sites and import edges, with file:line), never from symbol-name coincidence, so a CVE with no import evidence reports as unknown rather than reachable. Strong precision by construction; real-CVE recall on unfamiliar repos is still being measured — use it as a high-precision triage signal, and treat "unknown" as unverified rather than safe. -
Taint packs (
roam taint) — validated on synthetic fixtures; real-code recall on arbitrary repositories is low/unmeasured. Treat findings as leads to investigate, not a completeness guarantee; the--cigate is opt-in. -
Idiom & long-tail detectors (
roam auth-gaps,roam missing-index,roam over-fetch,roam n1, framework idioms) — advisory. Blind precision on unfamiliar repos is not yet measured for all of them, and framework idiom detectors that measured low on stranger repos are opt-in (not on the default surface). Review each finding; don't gate CI on these alone.
Core commands
Start with these five commands. Use understand, context, retrieve, preflight, and critique for everyday exploration and change review. You can discover the rest as you need them: 287 commands (280 canonical + 7 aliases) organised into 7 categories. An alias is another name for the same command; you do not need to memorize them. Explore the remaining 282 commands when you need more detail.
| Verb | What it does |
|---|---|
roam understand | Get an overview of the project and where to start reading |
roam context <symbol> | Read a definition alongside the code that calls it and the code it calls |
roam retrieve "<task>" | Find useful code for a question such as “trace the login flow” |
roam preflight <symbol> | See what a change could affect, including connected code and tests |
roam critique | Review a patch for related code you may have missed; pipe in git diff. High-severity findings exit 5 |
The full surface spans 7 categories — Getting Started, Daily Workflow, Codebase Health, Architecture, Exploration, Reports & CI, and Refactoring. Run roam --help for the 5-verb core, roam --help-all for every command name, and roam surface --json for the machine-readable inventory. Every command accepts roam --json <cmd> for structured output and roam --sarif <cmd> for CI integration (SARIF 2.1.0, honoured by 39 commands).
Full command reference — canonical command list (all 280)
The complete, always-current list with flags and examples lives in the Command Reference.
A few representative commands beyond the core five:
- Health & architecture:
roam health(0-100 score),roam weather(churn × complexity hotspots),roam smells(24 deterministic detectors),roam algo(34-task anti-pattern catalog),roam clusters/roam layers/roam cycles. - Change safety:
roam impact <symbol>(blast radius),roam diff(uncommitted-change blast radius),roam pr-risk(0-100 PR risk),roam diagnose <symbol>(root-cause ranking). - Backend quality:
roam n1(N+1 queries),roam auth-gaps,roam missing-index,roam over-fetch,roam taint(graph-reach taint, 11 rule packs). - Index-aware search:
roam search <pattern>,roam grep <pattern> -C 5(grep + bounded code packets + reachability + PageRank),roam grep <pattern> --whole-symbol(deduplicated enclosing functions/classes),roam uses <name>(graph-precise references, no string-literal false positives). - Multi-agent:
roam orchestrate --agents 3(conflict-aware partitioning),roam fleet plan,roam lease(parallel-agent coordination).
Walkthrough
10-command walkthrough investigating Flask (click to expand)
How you'd use Roam to understand a project you've never seen before, using Flask as an example.
$ roam understand                       # briefing: languages, stack, layers/clusters, health, key abstractions, entry points
$ roam file src/flask/app.py            # file skeleton: definitions + signatures + health
$ roam deps src/flask/app.py            # what imports this file
$ roam weather                          # hotspots ranked by churn × complexity
$ roam health                           # composite 0-100 + god components / cycles / layer violations
$ roam context Flask                    # AI-ready context: files to read with line ranges
$ roam preflight Flask                  # pre-change gate: blast radius + tests + complexity + fitness
$ roam split src/flask/app.py           # internal symbol groups + extraction suggestions
$ roam why Flask url_for Blueprint      # role classification (Hub/Bridge/Core) + reach + risk
$ roam health --gate                    # CI quality gate (exit 5 on failure)
Ten commands. Complete picture: structure, dependencies, hotspots, health, context, safety checks, decomposition, and CI gates.
Integration with AI coding tools
Roam is designed to be called by coding agents. Instead of repeatedly grepping and reading files, the agent runs one roam command and gets a verdict-first envelope. roam preflight (above) replaces grep+read+test-impact+complexity+fitness in one ~3KB call; roam health rolls the whole codebase into one score:
$ roam health
VERDICT: Fair codebase (77/100) — 65 critical, 0 warnings, focus: god_components

Health Score: 77/100  |  Tangle: 0.0% (0/44056 symbols in cycles)
Propagation Cost: 6.0%  |  Algebraic Connectivity: 0.0146

Health: 65 issues — 65 CRITICAL, 37 INFO
  (0 actionable cycles, 37 local/test cycles ignored, 50 god components
   (19 actionable, 31 expected utilities), 15 bottlenecks (2 actionable))
  Breakdown: cycles [0 issues], god [50 CRITICAL], bottlenecks [15 CRITICAL], layers [0 issues]

Top CRITICAL issues (run `roam --detail health` for the full breakdown):
  god component: result (prop, degree=2198)
  god component: path (prop, degree=677)
The verdict line works alone — an agent that reads nothing else still knows where to look. Pipe --json for the structured envelope your agent consumes.
Fastest setup (Claude Code): wire the compile/verify loop in one command — no config files, no MCP setup, no rules to write:
roam hooks claude --write # compile-before + verify-after hooks; --uninstall to undo
For other agents (or alongside the hooks), point them at Roam via instructions in their config file:
roam describe --write               # auto-detects CLAUDE.md, AGENTS.md, .cursor/rules, etc.
roam describe --agent-prompt        # compact ~500-token prompt — copy-paste into an existing config
roam minimap --update               # inject/refresh an annotated codebase minimap (won't touch other content)
This teaches the agent which command fits each situation: roam preflight before changes, roam context for files to read, roam diagnose for debugging.
Where to put agent instructions for each tool
| Tool | Config file |
|---|---|
| Claude Code | CLAUDE.md in your project root |
| OpenAI Codex CLI | AGENTS.md in your project root |
| Gemini CLI | GEMINI.md in your project root |
| Cursor | .cursor/rules/roam.mdc (add alwaysApply: true frontmatter) |
| Windsurf | .windsurf/rules/roam.md (add trigger: always_on frontmatter) |
| GitHub Copilot | .github/copilot-instructions.md |
| Aider | CONVENTIONS.md |
| Continue.dev | config.yaml rules |
| Cline | .clinerules/ directory |
MCP Server
Roam includes a Model Context Protocol server for direct integration with MCP-aware tools. See protocol compatibility, the agent CLI guide, and container installation and release evidence for supported versions and bounded examples.
pip install "roam-code[mcp]"
roam mcp
Default preset: core (17 tools: 16 core + roam_expand_toolset meta-tool).
246 MCP tools span 8 selectable presets (core, review, refactor, debug, architecture, compliance, compile-curated, full); core stays narrow to keep the prompt tight. Most tools are read-only index queries; side-effect tools are explicitly annotated. Set ROAM_MCP_PRESET=full roam mcp for the complete toolset.
When a tool cannot finish. MCP tools report missing prerequisites and
incomplete work in a structured response, with a status, explanation, and next
step. Consumers should check partial_success and errors, not just whether
the tool returned a response.
MCP runtime security. Three controls run at the wrapper boundary inside the server, protecting every client even with no gateway present: egress secret-redaction, mode-gated policy_decision enforcement (opt-in shadow-mode via ROAM_MODE_DRY_RUN), and HMAC-linked decision receipts bound into the signed run ledger. Mixed query/write tools are classified per invocation, so a read-only form stays available while an explicit persist/write flag raises the required mode and receipt effects. Gateway integrators: see dev/MCP-SECURITY-POSTURE.md.
See Using Roam via MCP for the first-run flow and canonical agent sequence.
Core preset tools: roam_alerts, roam_ask, roam_batch_search, roam_coupling, roam_dead_code, roam_deps, roam_diagnose_issue, roam_fetch_handle, roam_file_info, roam_grep, roam_metrics, roam_prepare_change, roam_search_symbol, roam_taint, roam_understand, roam_uses.
roam_ask (and roam ask on the CLI) is a natural-language codebase question dispatcher — 'is it safe to delete X?', 'where does login validate?', 'who owns module Y?' — that routes intent to one recipe in the graph-aware 31-recipe registry, replacing a Grep+Read round trip with one call.
The full 246-tool table with descriptions lives in docs/mcp-tools.md.
MCP client setup (Claude Code / Claude Desktop / Cursor / VS Code)
Prerequisite for every client below: Python 3.10+ and pip install "roam-code[mcp]".
Each config launches the roam binary from your PATH; if roam is not installed the
server exits with command not found before it can report anything more useful.
Claude Code: claude mcp add roam-code -- roam mcp, or add to .mcp.json:
{ "mcpServers": { "roam-code": { "command": "roam", "args": ["mcp"] } } }
Claude Desktop — add to claude_desktop_config.json (include "cwd": "/path/to/your/project").
Cursor — add the same mcpServers block to .cursor/mcp.json.
VS Code + Copilot — add to .vscode/mcp.json under a servers key with "type": "stdio".
Which preset ships where. The Claude Code plugin (.claude-plugin/plugin.json) pins
ROAM_MCP_PRESET=core — a consumer wants a tight prompt surface. This repo's own
.mcp.json pins full on purpose: agents working on roam-code dogfood the entire
246-tool surface. The two files name the same server and disagree deliberately; the split
is pinned by tests/test_distribution_manifests.py so neither drifts into the other.
Go deeper
Pick the path that matches your role:
- 5-min demo (CTO/CISO/dev-tools-lead): The Canonical Demo — install → health → preflight → critique → signed
ChangeEvidencepacket, five commands, no laptop egress. - Developer tutorial (15 min): Getting Started — install, index, query, ship.
- Agent integration:
roam mcp-setup claude-code --write(orcursor,windsurf,vscode,gemini-cli,codex-cli) — then Using Roam via MCP for the cold-start envelope and canonical agent loop. - Full surface: Command Reference — every command, flag, and JSON envelope.
- Architecture: How it fits together — graph, findings registry, run ledger, evidence compiler.
CI/CD integration
All you need is Python 3.10+ and pip install roam-code.
# .github/workflows/roam.yml
name: Roam Analysis
on: [pull_request]

jobs:
  roam:
    runs-on: ubuntu-24.04
    steps:
      - uses: actions/checkout@34e114876b0b11c390a56381ad16ebd13914f8d5 # v4.3.1
        with:
          fetch-depth: 0
          persist-credentials: false
      # For production, replace the tag with the reviewed 40-character SHA it
      # points at — a release tag is readable but remains movable.
      - uses: Cranot/[email protected]
        with:
          version: '14.0.4'
          commands: health
          gate: "score>=70"
          sarif: 'true'
          comment: 'true'
Generate this workflow explicitly with roam init --with-ci=github or
roam ci-setup --platform github --write; plain roam init does not modify CI configuration.
The Action accepts commands, gate (quality-gate expression, exit 5 on
failure), sarif (upload to GitHub Code Scanning), comment (sticky PR
comment), cache, and changed-only (incremental mode).
SARIF output. 39 commands honour the global --sarif flag (health, complexity, dead, smells, clones, vulns, taint, secrets, n1, …). Minimal upload:
- run: roam --sarif health > roam-health.sarif
- uses: github/codeql-action/upload-sarif@03e4368ac7daa2bd82b3e85262f3bf87ee112f57 # v3.36.0
  with:
    sarif_file: roam-health.sarif
For GitLab / Jenkins / Azure / Bitbucket templates, severity gates, and upload guardrails, see docs/ci-integration.md.
Roam Guard for PRs
roam guard-pr collects the current change's review record in one command:
what changed, which checks were required, which ran, and why the result is
pass, pass_with_warnings, needs_review, or blocked. The saved JSON
record is called an Agent Change Proof Bundle v1. It records available
evidence; it does not independently authenticate every supplied claim.
# Local — show the markdown verdict for your current branch's pr-bundle.
roam guard-pr --format markdown

# CI — one line; --ci is shorthand for --strict + --init-if-missing + markdown.
roam guard-pr --ci --output guard.md

# CI — post to GitHub Check Runs (works with the default GITHUB_TOKEN).
roam guard-pr --post-check --gh-repo $REPO --gh-sha $SHA
Example reviewer markdown:
## 🛑 Roam Guard verdict: `blocked`

> **0** of **4** required checks ran. **4** missing. Risk: `low`.

### Verdict reasons
- `required_checks_not_run` (×4) — `because=config_file_changed`
  - `lint.make.lint` (detail=['.mcp.json'])
  - `test.make.test` (detail=['.mcp.json'])

### Verification checks
| Status | Command | Why |
|---|---|---|
| 🛑 missing | `lint.make.lint` | config_file_changed |
| 🛑 missing | `test.make.test` | config_file_changed |
Verdict → CI exit + GitHub conclusion map. Exit codes are only emitted under
--strict (which --ci implies); without it guard-pr always exits 0 and the
verdict is reporting-only, so a CI gate must pass --ci or --strict:
| Roam verdict | Exit code (--strict / --ci) | Exit code (default) | GitHub conclusion | Build status |
|---|---|---|---|---|
pass | 0 | 0 | success | ✅ green |
pass_with_warnings | 0 | 0 | neutral | 🟡 yellow |
needs_review | 4 | 0 (+ stderr banner) | action_required | 🟠 attention |
blocked | 5 | 0 (+ stderr banner) | failure | 🛑 red |
A reporting-only run never passes silently. When the verdict would have
gated (needs_review / blocked) but no --strict/--ci was given, guard-pr
writes a loud banner to stderr naming the flag and the exit code it
suppressed, and the --json envelope carries the same fact in
summary.gate_enforced, summary.gate_suppressed and
summary.verdict_exit_code. Check gate_suppressed, not exit_code, if you
need to tell "verdict was clean" from "verdict was blocking but this run
wasn't gating" — exit_code is 0 in both cases.
// faq
What is roam-code?
Local codebase intelligence CLI + MCP server for AI coding agents: SQLite code graph, 28 languages, 287 commands, 246 MCP tools, change-safety gates, audit evidence, zero API keys.. It is open-source on GitHub.
Is roam-code free to use?
roam-code is open-source under the Apache-2.0 license, so it is free to use.
What category does roam-code belong to?
roam-code is listed under mcp-servers in the Claudeers registry of Claude-compatible tools.
// embed badge

[](https://claudeers.com/roam-code)
// retro hit counter

[](https://claudeers.com/roam-code)
// reviews
// guestbook
// related in MCP Servers
 🔓
f.k.a. Awesome ChatGPT Prompts. Share, discover, and collect prompts from the community. Free and open source — self-host for your organization with complete…
 🔓
A cross-platform desktop All-in-One assistant for Claude Code, Codex, OpenCode, OpenClaw, Gemini CLI & Hermes Agent. Only official website: ccswitch.io
 🔓
🪨 why use many token when few token do trick — Claude Code skill that cuts 65% of tokens by talking like caveman
 🔓
An open-source AI agent that brings the power of Gemini directly into your terminal.