
paranoid
Your app is guilty until proven secure: an agent skill whose /hack-me breaks into your own running app, proves each bug with a real request, patches it, and…
Install with your AI
Paste into Claude Code, Cursor, or any agent — it reads the repo and wires the tool into your project.
Install and set up paranoid (git-clone project) into my current project.
Found on https://claudeers.com/paranoid
Repo: https://github.com/kulchankas/paranoid
Homepage/docs: —
Detected install method: git-clone → git clone https://github.com/kulchankas/paranoid
Category: skills. Platforms: cli, api, web.
Read the repo's README for exact setup and env vars, then install it and wire it into my project.

Claudeers Health Verdict:
active; community-verified: false. Confirm the source before running anything.
git clone https://github.com/kulchankas/paranoid
// compatibility
| Platforms | cli, api, web |
|---|---|
| Operating systems | — |
| AI compatibility | claude |
| License | MIT |
| Pricing | open-source |
| Language | Python |
🕵️ paranoid
Your app is guilty until proven secure. /hack-me breaks into your own
running app, proves each hole with a real request, patches it, and re-verifies —
on localhost, with receipts.
paranoid is an agent skill for Claude Code, Codex, and Cursor. Its core is
/hack-me — an authorized, localhost-only self-pentest loop that attacks
your own app the way an attacker would, then closes what it finds.
find → prove → patch → re-verify
Why this isn't another "write secure code" skill
I started with the obvious thing — a skill that tells the agent to write secure
code — and then benchmarked it honestly before believing in it. The harness
(benchmark/) generates the same tasks with and without the skill
and runs real exploits against whatever the model writes.
The result was a clean negative:
| Model | Tasks | Exploit rate without skill | with skill | Effect |
|---|---|---|---|---|
| Fable 5.1 | isolated functions (easy) | 0% | 0% | none |
| Opus | isolated functions (easy) | 0% | 0% | none |
| Opus | isolated functions (neutral/tempting) | 0% | 0% | none |
On an isolated function, a capable model already writes the secure version
unprompted — ownership in the WHERE clause, parameterized queries, field
allow-lists — with no skill at all. Advice adds nothing there. (The harness
isn't rigged: it flags deliberately-insecure reference code at 100% and secure
code at 0%.)
Real vulnerabilities don't live in one tidy function. They live in the wiring
of a whole running app: auth on one route but not the next, a request body that
quietly sets is_admin, a search box that concatenates SQL. A model can't hold
all of that in its head while coding. So paranoid stops advising and starts
attacking the running app.
/hack-me, proven
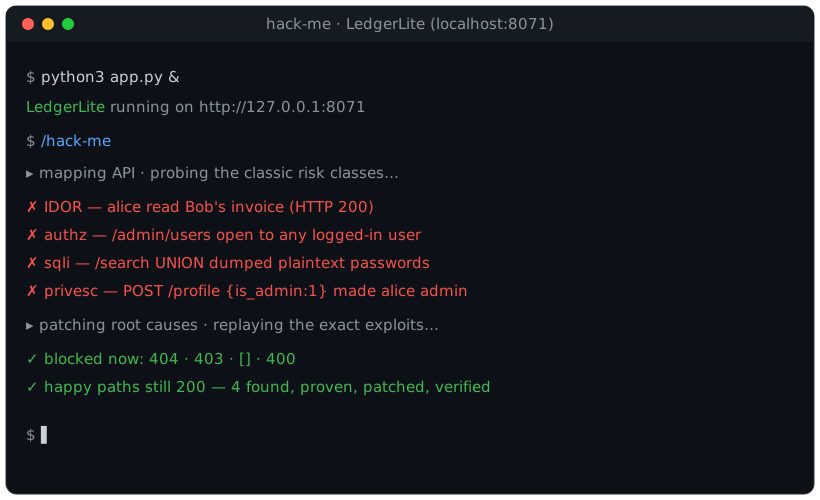
Against a small but realistic invoicing API (examples/ledgerlite),
a hack-me agent that was told nothing about the app's bugs found four by
probing, proved each with a live request, patched them, and re-verified:
| # | Found by probing the API | Class | Proof | After patch |
|---|---|---|---|---|
| 1 | Any user reads any invoice | IDOR / broken object auth | HTTP 200 with another user's invoice | 404 |
| 2 | /admin/users open to anyone logged in | broken function auth | full user directory dumped | 403 |
| 3 | /search?email= SQL injection | SQLi | plaintext passwords dumped via UNION | [] |
| 4 | /profile accepts is_admin | mass assignment → privilege escalation | regular user became admin | 400 |
Every legitimate request still returns 200 after the fixes. The full
walkthrough — exact exploit requests, responses, diffs, and re-verification — is
in examples/ledgerlite/HACKME_REPORT.md.
Reproduce it: python3 examples/ledgerlite/app.py, then run /hack-me.
That target was written as a demo, so it proves the loop works end-to-end. Point
/hack-meat your app for your own results.
Proven on an app we didn't write
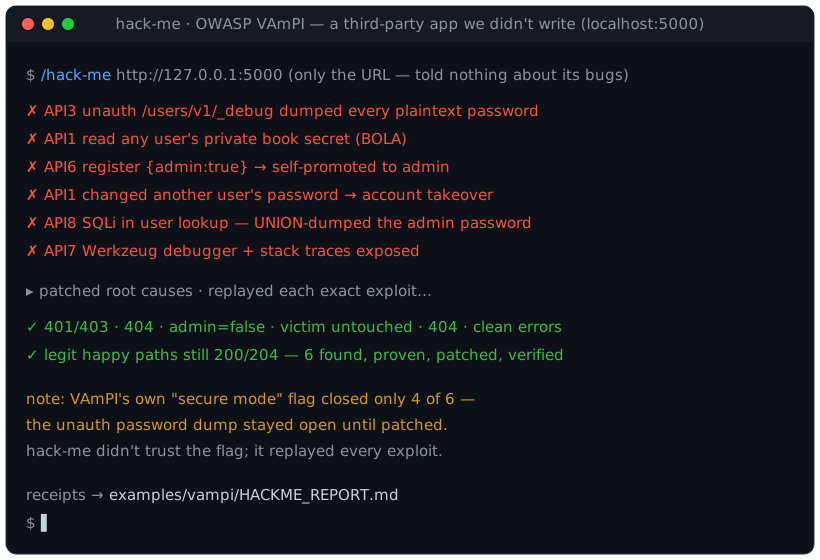
The harder claim is code we don't control. Pointed at OWASP VAmPI
— a well-known third-party vulnerable API — with nothing but its URL, /hack-me
found, proved, patched and re-verified six real bugs, including SQL-injecting
the admin's password out through the API and an unauthenticated endpoint dumping
every user's plaintext password:
| # | Finding | OWASP API | Status |
|---|---|---|---|
| 1 | Unauth /users/v1/_debug dumps every password | API3/5 | 401/403 |
| 2 | Read any user's private book secret (BOLA) | API1 | 404 |
| 3 | Register with admin:true → privilege escalation | API6 | admin=false |
| 4 | Change any user's password (account takeover) | API1 | victim untouched |
| 5 | SQLi in user lookup (UNION-dumps passwords) | API8 | 404 |
| 6 | Debugger + stack traces exposed | API7 | clean errors |
Notably, VAmPI's own global "secure mode" flag closed only four of the six — the
critical password dump stayed open until patched. /hack-me caught it by
replaying every exploit instead of trusting the flag. Full receipts:
examples/vampi/HACKME_REPORT.md.
What /hack-me actually does
- Maps your running app and picks the risk classes it's exposed to.
- Probes for each — one crafted request that only succeeds if the bug is real.
- Proves every finding with the actual request/response (no theorizing).
- Patches the root cause with a minimal, behavior-preserving fix.
- Re-verifies by replaying the exact exploit — a finding isn't closed until it fails.
Guardrails, always: your own / authorized targets, localhost only,
non-destructive proofs. It won't touch third-party hosts, evade detection, or
build live malware. See commands/hack-me.md.
Install
npx skills add kulchankas/paranoid/skills/paranoid
Then copy commands/hack-me.md into your agent's commands
dir (e.g. .claude/commands/) so /hack-me is available. No dependencies, no
network calls, no telemetry — it's Markdown your agent reads.
python3 my_app.py            # start your app locally
/hack-me                     # point the agent at http://localhost:<port>
Also inside: the paranoid skill (secure-by-default companion)
The guidance the benchmark tested still earns its place as a companion while
you code and as hack-me's knowledge base — concrete failure modes and fixes
for the vulnerability classes that actually ship in vibe-coded apps:
- the vibe-coded top 10
- references: auth & access ·
secrets & the client boundary ·
injection & SSRF ·
APIs & webhooks ·
/hack-meframework guides - a 7-point pre-commit gate
Load it while building; run /hack-me to check whether it held.
The benchmark
An honest, reproducible harness for the question "does a security skill actually
reduce vulnerabilities?" — plus the negative result above and how to re-run it:
benchmark/.
Scope & ethics
paranoid secures your code and pentests your running app, with your
say-so. It is not built to target third-party systems, scan hosts you don't own,
evade detection, or produce live malware, and it will decline to. Authorized,
defensive, local.
Roadmap
-
/hack-meloop — find → prove → patch → re-verify, on localhost - Reproducible skill-efficacy benchmark + the honest result behind the pivot
- Independent-app proof — OWASP VAmPI: 6 real bugs found, fixed & re-verified
- More benchmark task classes — 18 now (IDOR, missing auth, SQLi, mass assignment, path traversal, SSRF, XSS, command injection, open redirect, JWT auth, leaked secrets, CSRF, template injection, XXE, unrestricted upload, permissive CORS, weak password storage)
-
/hack-meframework guides (Next.js, FastAPI, Express)
paranoid is v0.1 and actively developed — issues and PRs welcome.
Contributing
New vulnerability classes, framework guides, and independent-app proofs are the most useful contributions — see CONTRIBUTING.md for the format and the honesty rules, and SECURITY.md for scope. Good first issues are labeled in the tracker.
License
MIT © 2026 kulchankas. See LICENSE.
// faq
What is paranoid?
Your app is guilty until proven secure: an agent skill whose /hack-me breaks into your own running app, proves each bug with a real request, patches it, and re-verifies. Claude Code · Codex · Cursor.. It is open-source on GitHub.
Is paranoid free to use?
paranoid is open-source under the MIT license, so it is free to use.
What category does paranoid belong to?
paranoid is listed under skills in the Claudeers registry of Claude-compatible tools.
// embed badge

[](https://claudeers.com/paranoid)
// retro hit counter

[](https://claudeers.com/paranoid)
// reviews
// guestbook
// related in Claude Skills
 🔓
An agentic skills framework & software development methodology that works.
 🔓
 🔓
💫 Toolkit to help you get started with Spec-Driven Development
 🔓
AI coding assistant skill (Claude Code, Codex, OpenCode, Cursor, Gemini CLI, and more). Turn any folder of code, SQL schemas, R scripts, shell scripts, docs,…