
ffmpeg-skill
Local video editor for coding agents: 42 FFmpeg tools with a machine-readable contract and an MCP server, for Claude Code, Cursor and Codex. Cut, captions, r…
Install with your AI
Paste into Claude Code, Cursor, or any agent — it reads the repo and wires the tool into your project.
Install and set up ffmpeg-skill (claude-plugin project) into my current project.
Found on https://claudeers.com/ffmpeg-skill
Repo: https://github.com/kajisho5/ffmpeg-skill
Homepage/docs: https://www.npmjs.com/package/ffmpeg-skill
Detected install method: claude-plugin → /plugin install ffmpeg-skill@kajisho5/ffmpeg-skill
Category: mcp-servers. Platforms: cli, api, desktop, mobile.
Read the repo's README for exact setup and env vars, then install it and wire it into my project.

Claudeers Health Verdict:
active; community-verified: false. Confirm the source before running anything.
/plugin marketplace add kajisho5/ffmpeg-skill
/plugin install ffmpeg-skill@kajisho5/ffmpeg-skill
git clone https://github.com/kajisho5/ffmpeg-skill
// compatibility
| Platforms | cli, api, desktop, mobile |
|---|---|
| Operating systems | — |
| AI compatibility | claude |
| License | MIT |
| Pricing | open-source |
| Language | Python |


Give your coding agent a video editor.
Claude Code, Cursor, Codex or any MCP client edits your footage with local FFmpeg, then checks its own output.
No cloud · No API keys · Python standard library
Quick start · Demos · Tools · MCP · npm
npx ffmpeg-skill
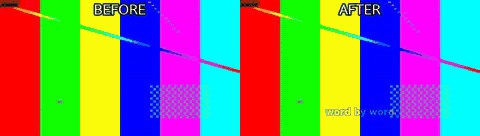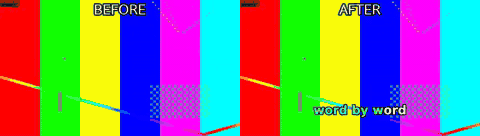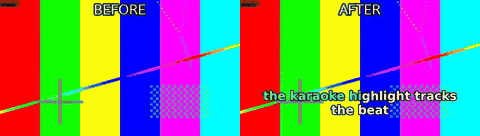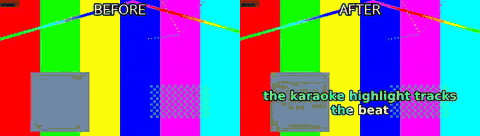 caption.py --animate pop --karaoke |  fit.py --aspect 9:16 --fit crop |
 silence.py --threshold -35 | 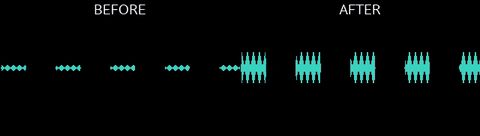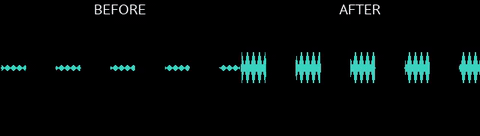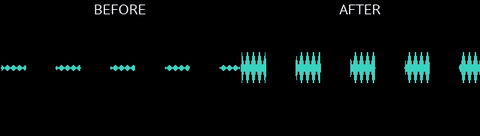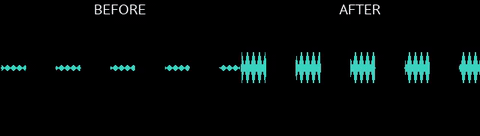 loudness.py -I -14 --tp -1 |
Left half is the input, right half is what the command produced. All 53 before/after demos, with the exact command under each one → — all of it generated from synthetic footage by python3 demos/build.py, so you can rebuild every frame of it yourself.
ffmpeg-skill is an Agent Skill for Claude Code, Cursor, Codex and any agent that reads SKILL.md. It teaches the agent a fixed workflow (probe → edit losslessly where possible → check → verify) and ships 42 tools that do the actual work with ffmpeg / ffprobe: cut, join, silence removal, fit to duration and aspect, captions and karaoke, overlays and motion graphics, HDR → SDR and LUTs, audio clean-up and typed dynamics, sync with drift correction, multicam, loudness, delivery checks, whole-edit project rendering, batch folders. Every tool is also callable as an MCP tool (tools/list advertises a core 12 by default to keep client context small, with FFMPEG_SKILL_MCP_FULL=1 listing all 42; every tool is reachable by name through tools/call either way), and the whole set is described by a machine-readable contract.
If ffmpeg and python3 are on your PATH, it works: offline, on footage you would rather not upload.
SPEC (Self-Producing Execution Contract): each tool's
input_schema— the part of its contract and MCP tool definition that has to track the CLI flag-for-flag — is never hand-authored beside the code. It is derived, at run time, from the sameargparseparser that already defines the CLI, and CI fails the build if any of it drifts. → full explanation
Standalone, and in an ecosystem
Standalone, this is a local FFmpeg engine: probe → edit → verify, npx ffmpeg-skill and nothing else. No API key, no account, no other repo required. Everything above and below this section describes that standalone tool, and none of it changes if you never read the rest of this one.
In kajisho5's wider video-production ecosystem, this repo is the hands: it cuts, measures and exports files, and reports back in structured JSON. It does not decide what to cut, whether a deliverable is approvable, what makes a highlight interesting, or what a caption should say (the user's cue text is burned as written, never rewritten to fit) — those are a brain's job, sitting in front of this engine, not inside it.
| You want to... | Use |
|---|---|
| Cut / join / measure / export a file right now | this repo (ffmpeg-skill), standalone |
| Decide cut points, approve a deliverable, plan a whole edit | video-production-agent / AI-video-production-OS |
Build a typed editing graph across a workspace, without writing raw ffmpeg | video-editing-skill / audio-production-skill |
Other repos in the ecosystem — media-analysis-skill, transcription-skill, subtitle-skill, thumbnail-skill, color-grading-skill, motion-graphics-skill, qc-skill — read this repo's contract --json, its tools' --json output and doctor, the same way any agent framework would; this repo does not call into any of them. The dependency runs one way.
Contents Standalone, and in an ecosystem · Why · Quick start · How it works · Design principles · Tools · Audio · Built for agents · FFmpeg compatibility · Tested on real footage · Install · Requirements · Development · Docs
Why
An agent that "knows FFmpeg" still guesses: it assumes a frame rate, picks a codec the container cannot hold, re-encodes a file that only needed a stream copy, and reports "done" without opening the result. This skill takes the guessing out:
- Real files first. Every job starts with
probe.py; the agent decides from the measured duration, fps, resolution, colour and audio layout, not from the file name. - Structured tools, not shell strings. Each operation is a script with typed arguments. Nothing runs through a shell; no filter graph is accepted from the caller.
- A contract the agent can read.
contract --jsonstates, for every tool, what it takes, what it writes, which FFmpeg components it needs and how the result is verified. The MCP surface is derived from it. - Verification after execution. The result is probed, checked against the destination's spec and, when the picture changed, looked at as a contact sheet.
- Local first. No cloud, no API keys, no Python dependencies. Optional local transcription is used when a speech engine (Parakeet or a whisper) is installed, never required — by
caption.py --transcribeand, since 1.17, bysilence.py --filler --transcribe; both take a transcript you already have instead, and both refuse with the install lines rather than guessing. Both take--engineand--model;FFMPEG_SKILL_ASR_ENGINEandFFMPEG_SKILL_ASR_MODELset this machine's defaults (e.g.large-v3-turbowhere that whisper.cpp model is installed; without either, auto andbase). The engine runs on your machine and the audio is never uploaded; parakeet-mlx, faster-whisper and openai-whisper download their model weights the first time they run (parakeet-mlx's default from Hugging Face).
Quick start
# 1. install the skill for Claude Code (Cursor: --cursor, Codex: --codex, all three: --all)
npx ffmpeg-skill

# 2. check the machine: ffmpeg, ffprobe and every FFmpeg component the tools need
npx ffmpeg-skill doctor

# 3. (for agent frameworks) read the machine-readable contract
npx ffmpeg-skill contract --json | head -40
Already installed? re-run npx ffmpeg-skill to refresh ~/.claude/skills/ffmpeg-skill. Copies are not updated automatically.
doctor's overall ok and a single tool's usable: no are different signals: ok means nothing required by every tool is missing, but a plain Homebrew ffmpeg on macOS can still be ok while caption.py specifically can't run (no subtitles filter) — check doctor --json's tools field for the per-tool answer, not just ok.
Then talk to your agent:
"Take
interview.mp4, keep 0:45–3:10 and 5:00–6:30, and make it exactly 60 seconds for Reels."
The agent runs probe.py, cut.py --segments 0:45-3:10,5:00-6:30, fit.py --duration 60 --aspect 9:16 --fit crop, export.py --preset reels, check.py --platform reels and look.py, then reports "final.mp4: 59.98 s, 1080×1920, 30 fps, AAC stereo" with the contact sheet it inspected.
Deliver to a platform
One command per destination, with the app's own UI taken into account:
python3 $S/render.py talk.mp4 --template tiktok --cues cues.txt
That fills the shipped templates/tiktok.json: 9:16 crop, captions popped word by word above
TikTok's description bar and clear of its like column, −14 LUFS, the tiktok export preset, and
a check.py --platform tiktok on the file it wrote. The caption size comes from the delivery
table, so since 1.17.1 the filled project also states "fit_size": "on": a size nobody asked for
shrinks to fit the cue instead of splitting the sentence across two cues. A template that states
its own fit_size, and a --brand that states a caption size, still win, and a project with
"fit_size": "off" renders the captions 1.17.0 rendered. Templates ship for tiktok, reels,
shorts, youtube-shorts, youtube, x, linkedin, facebook and podcast;
--template all (or a comma-separated list) renders every destination from the same edit and
writes a <name>_pack.md table of what each one produced. Files land next to the input unless
-o says otherwise, and --dry-run shows every planned command rather than a result.
render.py --list-templates prints them with their frames, limits and safe zones. Alias
spellings work everywhere a platform is named (youtube-shorts = shorts, ig = reels,
twitter = x, fb = facebook).
The tools also work on their own, from any shell:
S=~/.claude/skills/ffmpeg-skill/scripts
python3 $S/probe.py input.mp4 --compact
python3 $S/fit.py input.mp4 --duration 60 --aspect 9:16 --dry-run    # print the plan, run nothing
python3 $S/export.py input.mp4 --preset reels --json                 # structured result with a probe of the output
On Windows in Git Bash, python3 is only on PATH if Python was installed from the Microsoft Store; a python.org install exposes python (or the py launcher) instead — replace python3 with python above if you see a "command not found". bin/install.js and doctor/contract already handle this for you; only the raw script examples above need it spelled out manually.
More requests and the commands behind them: examples/README.md. To see everything run end-to-end on generated footage: npm run demo (the gallery in docs/demos.md).
How it works
flowchart TD
U[User request] --> A[AI agent<br/>Claude Code · Cursor · Codex]
A -->|reads| S[SKILL.md<br/>workflow, request → tool map, report format]
A -->|runs| T[Structured tool<br/>scripts/<name>.py, typed argparse flags]
T --> C[Contract<br/>input schema · role · capabilities · verification policy]
C --> D[Capability detection<br/>doctor: available / missing / unknown]
D --> F[FFmpeg execution<br/>no shell, stream copy when possible]
F --> V[Verification<br/>probe · check · look.py contact sheet]
V --> R[Structured result<br/>--json: status, output, commands, probe]
R --> A
Over MCP the same tools are reached through a transport that holds no tool table of its own:
flowchart LR
M[MCP client<br/>Claude Desktop · Cursor · any client] --> P[mcp/server.py<br/>stdio JSON-RPC]
P -->|tools/list| C[Contract-derived ToolSpecs<br/>names · order · inputSchema]
P -->|tools/call| T[scripts/<name>.py]
C -.derived from.-> K[scripts/_contract.py]
T -.described by.-> K
Names, order and inputSchema in tools/list are translated from each tool's argparse parser at start-up, so a new flag or a new script appears in MCP with no edit to mcp/. A test copies the skill, adds, removes and edits a script, and reads tools/list again to prove it.
Design principles
These are the rules the skill file gives the agent and the code enforces.
- Probe first. No tool decides from the file name.
probe.pymeasures duration, fps (with variable-frame-rate detection), resolution, rotation, bit depth, HDR format including Dolby Vision, colour tags and every audio stream before anything is cut. - Lossless when possible.
cut.py,join.pyandloudness.pystream-copy what they do not need to touch. Re-encoding happens only when it must: frame-accurate cuts, filters, format changes, or a keyframe farther than the tolerance. - Plan before render. Every tool takes
--dry-run(print the ffmpeg command lines, write nothing),--plan FILE(the dry run saved as a plan with fingerprinted inputs thatrender.py FILEexecutes later, refusing if an input changed),--json(structured result with a probe of the output),--fast(preview quality),--progress(percent and ETA),--timeout(a hung ffmpeg is killed and reported, never waited on forever; Ctrl-C or SIGTERM likewise stops the running ffmpeg, removes its partial output and reportskind: interrupted) and--overwrite(explicit consent before an existing output is replaced). A test runs every tool under--dry-runbehind a fake ffmpeg and asserts that no ffmpeg call happened and no file appeared. - Machine-readable contract.
contract --jsondescribes all 42 tools: input schema generated from the parser, output schema, role, required and conditional FFmpeg capabilities, dry-run support, the verification tools to run afterwards, whether a visual check is required,mutates_input: false.provideslists all 42 by a cross-repository Capability id (ffmpeg-skill.cut,ffmpeg-skill.loudness, ...) forkajisho5/AI-video-production-OS'sCapabilityContract.provides— seedocs/contract.md. - Contract-derived MCP.
mcp/server.pybuilds itstools/listfrom the contract. Tool names, order andinputSchemacannot drift from the scripts; a test keeps the two byte-identical. - Capability detection.
doctorreadsffmpeg -encoders / -filters / -bsfsand reports which of the components the tools need are present on this build (libx264, libass, zscale, loudnorm, xfade, …), before a job fails inside ffmpeg. - Unknown is not missing. When a listing cannot be read (a layout the parser does not know, ffmpeg exiting non-zero) the affected capabilities are
unknown: nevermissing, never silentlyavailable. An installed filter is not reported absent; a failed detection is not a pass. - Verify the result. The output is probed, and when the picture changed (captions, overlays, crops, colour, transitions) the agent runs
look.pyand inspects the PNG. The report is not finished until itsLook:line names that image; audio-only jobs sayLook: not needed. "Inspects" means the calling agent's own vision, not a feature of this skill:look.pyonly renders a PNG; nothing in this repository detects faces, products, subjects, or "the interesting part" of a frame or a scene. When a crop or reframe needs to keep a specific part of the frame (fit.py --fit crop --crop-x/-y, see Tools), it is the multimodal agent looking at that PNG and choosing the anchor — a non-visual caller (a script, a CLI user without eyes on the sheet) has to supply that decision itself, and the default is a plain centre crop. Likewisescenes.py --highlightsranks candidate scenes by a measured proxy (--rank-by audioor--rank-by duration), never by content; it is the agent that turns a look at the sheet into a judgement. - One label per report. A finished job is
Done:, a failure or a refusal isFailed:, and a partial result isDone:with the shortfall named inNotes:— never a third label such asDone (partially):. - Keep originals. No tool overwrites its input. Outputs are new files named
<input>_<operation>.<ext>unless told otherwise, and a test hashes every input after the run.
Tools
42 public tools, all Python 3.9 standard library, all with --help, --dry-run, --json, --plan FILE (a dry run written as a plan render.py executes later), non-zero exit and a reason on stderr on failure. --json-brief (1.11.0) prints the same result document trimmed to what a caller acts on — status, output, verified, a compact summary of the output probe, the tool's own keys and the command count instead of the command lines — for roughly a third of the bytes; --json itself is unchanged. Every re-encoding tool takes --codec h264|hevc|av1|prores and --quality N (1.8) and, with export.py, --hw/--no-hw (Apple VideoToolbox on Apple Silicon, opt-in; see doctor below), and every time flag takes seconds, mm:ss, hh:mm:ss.fff or SMPTE hh:mm:ss:ff with an optional @fps suffix (1.9).
Analysis and inspection
| Tool | What it does |
|---|---|
probe.py | Duration, fps (+ VFR detection), resolution, codecs, bit depth, HDR format incl. Dolby Vision (hdr for a real PQ/HLG/DV transfer only, bt2020_or_hdr also for BT.2020 SDR), colour space, rotation, every audio stream; --analyze flags Log footage |
scenes.py | Scene changes, audio peaks, highlight proposals (--rank-by audio loudest, or --rank-by duration longest — both proxies, not "best") and a per-scene sheet; cut list for cut.py --segments; --beats measures the music's beat grid (tempo, beat times, confidence); --shots classifies each shot static/pan/motion by measured optical flow; --audio-peaks lists per-second dBFS; --speech reports a speech-vs-music ratio, not a classification |
look.py | Contact sheet, single frames, side-by-side comparison as PNG so the agent can see what it made; --safe NAME shades the zones a platform's own UI covers |
Editing
| Tool | What it does |
|---|---|
cut.py | In/out or multi-segment cuts, lossless -c copy first, re-encode fallback, --accurate for frame-exact video and sample-exact audio, --keep-hevc to re-encode an HEVC source as HEVC, --edit-list to keep an .mp4 copy's start exact, --vfr-guard to choose the VFR check; reports precision; --snap beats moves the in/out points onto a measured beat, or refuses when there is no measurable pulse |
join.py | Concatenate clips with xfade transitions, normalising size, fps, sample rate and channel layout (the widest clip's, or --channels); audio-only inputs are joined as audio; --list parts.txt reads generated segments (TTS lines) and checks every one first — missing, empty or unreadable parts are all named in one refusal, or skipped and reported with --on-missing skip |
silence.py | Detect and remove dead air (jump cuts) with a margin around speech; list or export the cut list; --filler also removes filler words, but only where a speech engine timed them; --speech-aware keeps a breath inside a sentence and cuts only at sentence-boundary pauses, composing with --filler through the same keep_ranges() |
fit.py | Fit to a duration (pitch-preserving speed change or trim, smooth slow-mo) and/or aspect ratio (pad, crop or --fit blur's blurred, darkened fill, with --crop-x/--crop-y to keep an off-centre subject) and/or exact --width/--height; rotate 90/180/270, flip h/v; force constant fps |
crop.py | Crop to an exact pixel rectangle (--x --y --width --height) — distinct from fit.py --fit crop, which crops to an aspect ratio it computes itself |
cropdetect.py | Measure existing black letterbox/pillarbox bars and report the crop.py-ready rectangle that removes them — analysis only, writes no file; --motion-centre reports the per-second motion centroid instead, for a 9:16 reframe — report only, the calling agent picks the crop, no auto-reframing |
deinterlace.py | Deinterlace interlaced source footage (yadif), --mode frame/field, --parity |
denoise.py | Reduce video noise/grain (hqdn3d), --strength low/medium/high or individual spatial/temporal overrides |
redact.py | Blur or pixelate an exact pixel rectangle for the whole clip (privacy/compliance redaction) |
sphere.py | Extract a flat rectilinear viewport from a 360/spherical video (--yaw --pitch --roll --h-fov --v-fov); no subject tracking, only the aim you give it |
straighten.py | Rotate by an arbitrary angle for horizon correction (--degrees, --fit crop/pad) — distinct from fit.py --rotate's exact 90-degree turns |
insert.py | Turn a still image into a silent, fixed-duration video clip (title card, end slate) at an exact frame size / fps, with an optional Ken Burns zoom/pan |
background.py | Generate a solid-colour or two-colour gradient clip at an exact size/duration — no input file |
reverse.py | Reverse playback (video and, unless --no-audio, audio) |
stabilize.py | Two-pass motion stabilisation (vidstabdetect/vidstabtransform) |
sequence.py | Numbered (frame_%04d.png) or glob-matched still images into a video |
waveform.py | Render an audio track as a waveform or spectrum visualization video (showwaves/showspectrum) — for audio-only inputs with no picture worth showing; --image puts the visualisation over a still plate (an audiogram), with --platform, --title and burnt-in captions |
freeze.py | Hold a frame for N seconds (--at, --hold, --mode insert/extend) — an end-card hold or a comedic beat |
pad.py | Add black/silent padding at the start and/or end of the timeline (--start, --end) — distinct from fit.py --fit pad's per-frame letterbox bars |
speedramp.py | Step through different constant speeds across a clip via --segment START-END:FACTOR (repeatable) — distinct from fit.py's single whole-clip speed factor |
loop.py | Repeat a clip --times N or to a target --duration — for background loops and filling a fixed slot length; --boomerang plays it forward then backward |
broll.py | Cut away to a B-roll clip over the A-roll for a window (--insert B --at T --duration D, repeatable) and come back; A's length and audio untouched by default |
metadata.py | Write container chapter markers from a TIME TITLE text file and title/artist/comment tags, every stream copied bit for bit; --auto-chapters proposes the markers from measured pauses and scene cuts and names them Chapter N for you to rename |
grid.py | Composite --colsx--rows clips into one grid, each cell letterboxed and labelled with its filename by default (--label none to skip) |
Audio
| Tool | What it does |
|---|---|
audio.py | Voice clean-up chain at three strengths (--voice light|medium|strong), FFT denoise, typed compressor / limiter / gate, music bed with sidechain ducking (--duck-amount/-threshold/-attack/-release), a never-ducked effects bed (--effects), --stereo-widen, fades, 5.1 → stereo, track replacement, extraction (-o out.wav), --audio-stream N |
sync.py | Offset between two recordings by audio cross-correlation (1 ms, pure Python), clock-drift correction; aligned video or audio out (audio-to-audio only — no lip-sync/face detection); a third or later camera is an additional more_sources positional (sync.py REF A B ...), the second positional itself keeps its name |
loudness.py | Two-pass EBU R128 loudnorm to −14 LUFS / −1 dBTP or any target (--lra for the range), video stream-copied; the written file is measured again and re-encoded until it meets --tp (lossy encoders overshoot); --measure-only |
Picture
| Tool | What it does |
|---|---|
caption.py | Burn SRT/ASS with font, size, colour, outline, position; build SRT from timed plain text; wraps to the safe area — with --platform, the destination's own left/right safe zone, which since 1.17.2 is also what the burnt ASS states as its side margins — with a phrase-aware breaker (`--wrap phrase |
overlay.py | Logos, watermarks and titles with position, time range, opacity, fades; --platform NAME keeps them clear of that destination's UI; --video for picture-in-picture, --chromakey for green-screen compositing |
graphics.py | Lower-thirds, title cards, chapter chips, progress bars, countdowns, corner bugs, social stickers, opening hook cards and meme captions drawn by FFmpeg from a brand kit; --platform NAME keeps them inside that destination's safe zone; --text-render routes shaping scripts through libass and --emoji-assets composites colour emoji |
color.py | HDR10 / HLG / Dolby Vision → SDR BT.709 tone mapping, DV layer stripping, 3D LUT (.cube), colour-tag rewriting, typed primary correction (exposure/contrast/saturation/gamma/white balance/lift-gain/levels/curves) |
Delivery
| Tool | What it does |
|---|---|
export.py | Presets youtube, youtube4k, reels, tiktok, shorts, linkedin, facebook, x, youtube-hdr (HEVC Main10, source HDR tags kept), youtube-av1, prores, h265, gif, copy, all tagged BT.709 unless they carry HDR (a BT.601-matrix or RGB source is converted to BT.709, not relabelled); --normalize meets the platform's loudness in the same call (render.py turns it on by default for platform presets) |
proxy.py | Small, low-bitrate proxy for downstream AI analysis/preview/editing decisions — resize by --width/--scale, proxy-grade --quality (default 30), --fps, --no-audio; not a delivery preset |
check.py | PASS / WARN / FAIL against YouTube, Shorts, Reels, TikTok, X, LinkedIn, Facebook, broadcast and podcast specs, from the same delivery table the export presets and templates read (podcast also reports chapter markers and channel count), with the fix for each failure and a format / judgement kind per row |
report.py | Single-file HTML delivery report: before/after sheets, media facts, loudness, compliance, the commands run; --pack renders a social pack table |
Orchestration
| Tool | What it does |
|---|---|
render.py | Render a whole edit from a declarative project.json (clips, transitions, captions, overlays including the social sticker/hook/meme graphics and a picture-in-picture or chroma-keyed video layer sized for the final frame, music and stem levels, loudness, export, chapter markers, check); --init, --dry-run, --stop-after, --cache DIR/--from STAGE (reuse the stages that did not change); the captions block takes the fit-size policy (fit_size, min_size, fit_size_scope) and the run reports the caption stage's counts as caption; --template NAME INPUT renders a shipped delivery template (--template all writes the whole social pack plus its table); --export-timeline edit.fcpxml|.edl|.otio (2.1) writes the cut as an editor timeline for Final Cut, DaVinci Resolve or Premiere instead of rendering it — clips, speed, dissolves, the music bed and chapter markers carry over, and not_exported names what stays behind |
batch.py | Apply a step recipe or a project to a folder with a content-hash cache; --watch; --jobs N processes several files at once under one shared --timeout |
multicam.py | Align any number of cameras and recorders by audio (with drift correction) and cut between them from a switch list; --switch energy auto-cuts to whichever camera is loudest/talking instead of a hand-built list, with --min-shot (minimum shot length) and --edl (write a plain START-END cut list, not a CMX EDL; for Premiere/Resolve use --write-project then render.py --export-timeline) |
verify.py | Run the toolchain on real device files and report PASS / FAIL per step |
Not tools, but part of the surface: mcp/server.py (the MCP transport) and scripts/_contract.py (contract --json, doctor). Per-flag reference for every tool: references/scripts.md.
Audio is a first-class input
WAV, FLAC, MP3, M4A/AAC, OGG and Opus go through probe, cut, join, silence, loudness, audio, sync and check --platform podcast with the same commands as video. The output extension picks the codec: -o out.wav writes PCM, -o out.flac FLAC, -o out.mp3 MP3, -o out.m4a AAC.
- Extraction. An audio extension on a video input drops the picture:
audio.py talk.mp4 -o talk.wav, or--voice -o talk.m4ato clean it on the way.--audio-stream Npicks a track;probelists them underaudio_streams. - Join.
join.py intro.wav episode.m4a outro.wav -o full.flacresamples every clip to one rate and channel layout and crossfades them (--transition nonefor a butt join). Audio and video inputs cannot be mixed in one join. - Sample-accurate trims.
cut.py talk.wav --start 1.2345 --end 2.3456 --accuratetrims at the sample; the JSON reportsprecision(packetfor a stream copy,samplefor PCM / FLAC,codec_framewhen a lossy encoder frames the audio again,framefor video) and the measuredduration_error_ms. A.wavnever receives compressed packets. - Typed dynamics.
audio.py --compress --comp-threshold -20 --comp-ratio 4,--limit --limit-ceiling -1,--gate --gate-threshold -45. Each flag is one documented option of FFmpeg'sacompressor,alimiteroragate, range-checked before ffmpeg runs; no filter string is accepted from the caller. - Loudness.
loudness.py talk.wav -I -16 --tp -1.5 -o talk.m4afor podcast levels;check.py talk.m4a --platform podcastmeasures LUFS and true peak and reports the chapter markers and channel count.
Picture tools (fit, caption, overlay, graphics, color, export, scenes, look) refuse an audio file with "input has no video stream" instead of inventing a picture.
Built for agents
What is SPEC?
SPEC (Self-Producing Execution Contract) is the name this project's author,
kajisho5, gave the pattern the tool layer is built on: each tool's
input_schema — the part of its contract that has to track the CLI exactly, flag for flag — is
never hand-authored side by side with the code. It is derived, at run time, from the one thing
that has to be correct for the CLI to work at all: the script's own argparse parser.
Concretely, scripts/_contract.py's _capture_parser() imports every tool script and
intercepts its parse_args() call to get the live, fully-built parser object — flags, types,
choices, defaults, required/positional, mutually exclusive groups, all of it. input_schema is
built straight from that object. (The rest of a ToolSpec — role, capabilities, inputs,
outputs, output_schema — comes from a hand-authored table, TOOL_META, since those facts
aren't things a parser can express; only input_schema is parser-derived.)
- The contract's
input_schemafor every tool is generated from the live parser directly. - SKILL.md is two-tier (1.11.0): the file the agent loads every session keeps the workflow, the
request→script table and one line per gotcha; the long-form detail lives in
references/gotchas.mdand the otherreferences/files, read only when a job needs it. - The MCP server (
mcp/server.py) carries no schema of its own;tools/listis translated straight from the contract,input_schemaincluded. - The docs (
docs/contract.md's field reference, this README's tool table) describe the same shape.tests/test_contract.pyruns on every CI run and fails the build if any of them drift out of sync with what the code actually does — it catches drift, it doesn't fix it for you.
So adding a flag to a script's argparse block updates input_schema and the MCP tool
definition with no second edit, and a docs page or TOOL_META entry that falls behind fails CI
rather than drifting silently. There is no separate input_schema file to forget to update.
Machine-readable contract
npx ffmpeg-skill contract --json            # or: python3 scripts/_contract.py --json
npx ffmpeg-skill contract --json --static   # without environment detection
The contract is generated from the code that runs, not maintained beside it. For each of the 42 tools (ffmpeg-skill/<name>) it states:
| Field | Meaning |
|---|---|
input_schema | generated from the tool's argparse parser: properties, types, enums, defaults, required, positional order, mutually exclusive groups |
output_schema | what --json prints: status, output, commands, probe, plus tool-specific fields (precision, checks, offset_seconds, …) |
role | analysis, analysis_and_execution, execution or verification |
capabilities | the FFmpeg encoders, filters and bitstream filters the tool always needs, and the ones needed only for a flag or input |
supports_dry_run, supports_json, supports_json_brief | measured by the tests, not declared |
verification | which tools to run on the output afterwards (probe, check, look) |
requires_visual_verification | the picture changed; inspect the contact sheet |
audio_only, video_required | whether an audio-only input is accepted or refused |
mutates_input | always false |
idempotency_hint | bit_exact, content_equivalent, cached or environment_dependent |
Next to the tool list the document carries a top-level deprecated list (1.10): what 2.0.0 removes, since when, the replacement and the surface it lives on. docs/contract.md "What 2.0 changes" is written from it.
contract_version (1.0) is separate from the skill version, so a consumer can pin the shape and read the version for provenance. The document also states the invocation mapping (structured arguments → argv), the JSON shapes for success and failure ({"status": "failed", "error": {"kind": "input | ffmpeg | output | missing_tool | timeout | verification | interrupted", "message": …}}), and that no tool runs a shell or executes anything other than the named script, ffmpeg and ffprobe. Field-by-field reference: docs/contract.md.
MCP
{"mcpServers": {"ffmpeg-skill": {"command": "python3", "args": ["/Users/you/.claude/skills/ffmpeg-skill/mcp/server.py"]}}}
On Windows, python3 is only on PATH if Python was installed from the Microsoft Store; a python.org install exposes python (or the py launcher) instead — if your MCP client reports the server failed to start, change "command" above to "python" (or the full path from where python).
mcp/server.py is a stdio JSON-RPC transport with no tool table of its own. tools/list is derived from the contract at start-up, in contract order, with inputSchema translated from each tool's input_schema. By default it lists only the core 12 (render, look, caption, export, check, fit, cut, audio, loudness, graphics, silence, probe) so a client doesn't pay context for 30 schemas it rarely calls directly; set FFMPEG_SKILL_MCP_FULL=1 to list all 42. Every tool, listed or not, is callable through tools/call, which maps structured arguments to argv and runs the named script; a raw argv form is accepted for compatibility and marked non-canonical. python3 mcp/server.py --list prints the tools; --call probe '{"inputs": ["a.mp4"]}' runs one from the shell.
No inputSchema lists json or progress: they are transport flags the server sets itself, not tool arguments (2.0; 1.x listed them unless FFMPEG_SKILL_MCP_LEAN=1). A client that still sends them is not refused.
The server also advertises a prompts capability: five canned workflow recipes an agent can ask for by name instead of composing the individual tool calls itself — reel, podcast, multicam, delivery_check, hdr. prompts/list returns each one's name, description and arguments; prompts/get {name, arguments} fills the matching template and returns one text message naming the actual command lines to run and what to check afterward. These are recipes, not new tool calls — every command line a prompt names is one tools/call (or the CLI) can already run.
Capability detection
npx ffmpeg-skill doctor          # human-readable
npx ffmpeg-skill doctor --json   # available / missing / missing_optional / unknown / detection / errors / tools / gpu_encoders
doctor reads ffmpeg -encoders, -filters and -bsfs and resolves every capability the contract declares against this machine's build. Three states per capability: available, missing, unknown. Exit 0 when everything required is available, 1 when something required is missing, 2 when nothing is proven missing but a required capability is unknown. With detection on (the default), contract --json carries the same lists under capabilities. doctor also reports fonts: the default drawtext family, and fonts.scripts — one available/missing/unknown per writing system (ja, zh, ko, ar, he, hi, th, ru, el) with the file it would use — so "can this machine render Korean captions" is answered before the job, not after. doctor --json's tools field folds that down to one answer per tool — {"caption": {"usable": "no", "missing": ["filter:subtitles"], "fix": "..."}, ...} — so "is doctor overall ok" and "can I run caption.py on this machine" are answered separately: a plain Homebrew ffmpeg is ok for tools that don't need subtitles/drawtext/zscale, while caption's own usable is "no".
doctor --json's gpu_encoders reports which GPU-backed encoders (nvenc, videotoolbox, qsv, vaapi, amf) this ffmpeg build was compiled with — read from -encoders alone, so it proves the capability shipped, not that the GPU/driver on this machine will actually accept a job (that needs a real encode, which doctor's introspection never runs). It never affects ok or any tool's usable. The one GPU path a tool uses is Apple VideoToolbox, opt-in: --hw on every re-encoding tool (h264/hevc/prores on the GPU, AV1 stays on SVT-AV1), FFMPEG_SKILL_HW=1 to make it this machine's default for everything except export.py's delivery presets (those take --hw explicitly, or render.py --hw for a whole project). It runs only on Apple Silicon and never by default, except on a build with no libx264/libx265 (an LGPL ffmpeg that has only h264_videotoolbox/hevc_videotoolbox): there it is the only encoder, so every re-encoding tool and export.py's presets use it without --hw, the result says hw.source: "auto", and doctor lists the missing x264/x265 under covered_by instead of calling the tools unusable (--no-hw still asks for the CPU). It falls back to the CPU encoder — reported in the result's hw.fallback/hw.notes — only when VideoToolbox itself refuses a job (any other ffmpeg failure is reported as it happened, not retried); every result names the encoder that actually ran (batch.py, which encodes nothing itself: each results row), and a GPU encode adds a notes line that its quality is not CRF-equivalent. Measured on an M4 Max, 2–7× faster than x264/x265 medium; at matched SSIM (tests/bench_vt.py) 1.1–2.9× the bytes on SDR and 1.9–3.5× on HDR, which is why it is a flag and not the default (docs/design-decisions.md). doctor --json's hw says whether this machine can run it (platform_ok) and whether it is the default here (default_on).
Gotchas and best practices
The short list for humans. The agent-facing version, with the reasoning, is the "Things that look right but are wrong" and "Gotchas" sections of SKILL.md.
- Variable frame rate (phone and screen recordings).
probe.pyflags it; every re-encoding tool conforms to a constant rate automatically.cut.pyswitches to frame-accurate mode on it, because copy-cuts on VFR land on the wrong frame, and samples the frame timing to say whether that was needed (--vfr-guard sampleddecides on the sample instead;--vfr-guard offkeeps the copy). Choose the rate yourself withfit.py input.mp4 --fps 30when the measured average is odd. - Lossless cuts snap to keyframes. A stream-copy cut can start up to one GOP earlier than asked.
cut.pyre-encodes when the snap exceeds 0.5 s (--tolerancechanges the limit). For a strictly lossless file pass--tolerance -1(plus--vfr-guard offon a variable-frame-rate source), and expect the cut to land on the nearest earlier keyframe; the JSON result lists them undernearest_keyframes. A--segmentsjoin can still be re-cut: open-GOP video, a later segment of B-frame.mp4/.movvideo that starts between keyframes (start it on a keyframe, or write.mkv), or a join that fails its check. For a single.mp4/.movcut,--edit-listkeeps the copy and starts the picture where asked: the keyframe's pre-roll is stored but hidden by an MP4 edit list, which a player that ignores edit lists shows. - HDR stays HDR. When the probe reports HDR (HDR10, HLG, Dolby Vision, BT.2020), the tools keep it rather than flatten it. Convert deliberately with
color.py --to-sdrbefore H.264 deliverables or LUT work.export.pyplatform presets are SDR and warn on HDR input. - Loudness targets. −14 LUFS / −1 dBTP for YouTube and social platforms (the
loudness.pydefault),-I -16 --tp -1.5for podcasts,-I -23for broadcast. A clip measured at −40 LUFS or below is room tone, not content; raising it raises the noise. Check true peak as well as LUFS:check.py file --platform podcastmeasures both. - Frame changes first, text second. Captions and overlays burned before a crop or resize end up off-frame. Reframe, then caption.
- Cropping 16:9 to 9:16 discards 70 % of the width.
fit.py --fit cropcentres by default; pass--crop-x/--crop-ytoward the subject, or pad with--fit pad --pad-fill blur. Look at the contact sheet before deciding. - Phrase-aware caption breaking (1.16).
caption.py/graphics.py --wrap phrase(the default) never breaks inside a word or on the wrong side of a hyphen, never leaves a lone digit, kana or punctuation pair on a line, prefers Japanese sentence ends and particles over a mid-word break, and never ends a line on an article or preposition. All four are penalties over break positions that already fit, so no line is widened and the line count never changes;--wrap measuredrestores 1.15's width-only wrap. The text itself is never rewritten or shortened. Since 1.16.1 a Thai run and a katakana word are never broken inside (Thai writes no space inside a phrase and there is no dictionary: the break goes where you put a space or|), and a line wider than the safe width is reported asoverlongwith the fix named. - Caption size fitted to the cue (1.17, reachable from the templates since 1.17.1). At a platform caption size a line holds about six em, so an ordinary sentence needs four lines and
--max-lines 2used to cut it into consecutive cues — half the sentence arriving late.caption.py --fit-size(defaultauto) walks the size down until every cue fits, before laying the cues out, with a legibility floor of 4.5 % of the frame height (--min-size, default 13 ASS units). An explicit--sizeor abrand.jsonsize is a statement about the look and is never overridden — which in 1.17.0 also silenced the fitter on everyrender.py --templaterun, since a template fills the size from the platform table; 1.17.1 marks that size as the default it is ("fit_size": "on"in the filled project), so the type shrinks and no cue is split.--fit-size offrestores that earlier behaviour byte for byte, and the caption text is still never rewritten to make it fit. - Beat-synced cuts (1.17).
scenes.py --beatsreports the measured grid — tempo, beat times, and a confidence built from how far the winning autocorrelation lag stands above the others and how many onsets land on it.cut.py --snap beats(and a"snap"block in arender.pyproject) moves in/out points to the nearest beat within--snap-tolerance— and only onto the grid points a measured onset actually marks, never onto the regular grid's continuation through a passage with no music in it. Below--min-confidenceit refuses: a cut point may move to a measured beat and may not appear from one, so speech and ambience get an honest "no steady pulse here" instead of an invented grid. - Filler words (1.17).
silence.py --filler --words transcript.jsonremoves "um" and "uh" through the same cut graph the silences use. Never without measured word timings — there is no heuristic that finds an "um" without them that would not also cut real speech — andlike,tipoandcioèare deliberately not in the built-in lists, because a discourse marker is a content word. Whisper stays optional:--transcribewith no engine installed refuses and names the five installs. - Throughput (1.17).
batch.py --jobs Nruns several files at once, capped atmin(N, cpu_count, 8)and sharing one--timeoutbudget rather than one per item; the per-item table keeps its order.render.py --cache DIRreuses stages whose inputs and arguments did not change, so swapping an export preset re-runs export only. The cache is opt-in with no default directory, and the ffmpeg, skill and contract versions are part of every key, so a cache is never reused across them. - Audiogram (1.16).
waveform.py --image cover.png(orrender.py --template audiogram) puts the waveform over a still plate for an episode that has no picture, with--platformfor the frame,--titleand burnt-in captions. The image is a local file you give: nothing is fetched and no cover art is ever invented. - Emoji in captions and titles (1.15).
caption.py/graphics.py --emoji-assets DIRcomposites a PNG per emoji (Twemoji/Noto naming,1f389.png) on top of the text, because drawtext cannot load a colour emoji font at all and an installed one does not prove libass will draw it in colour —doctor --json'sfonts.emojianswers that from a render probe. Without assets the run still succeeds and reportsmode: mono. Nothing is ever downloaded. - Indic and Thai text shaped correctly in titles and lower-thirds (1.15).
graphics.pyrenders Devanagari, Bengali, Tamil, Thai and Lao through libass automatically (text_renderer: "ass"), because drawtext never reorders matras or re-clusters marks; Arabic and Hebrew were already correct on a fribidi build.--text-render drawtextwith such a script is refused, never rendered wrongly. - Non-Latin text picks a font by script (1.12). Japanese, Chinese, Korean, Arabic, Hebrew, Devanagari, Thai, Cyrillic and Greek cues, titles and overlays resolve a font file that covers them automatically, and a machine with no such font fails the job (
kind: input) instead of rendering boxes.doctor --json'sfonts.scriptssays which languages this machine can render;--lang ja|kodisambiguates Han-only text; an explicit--font/--font-fileis always kept. - Silence detection finds nothing? The default threshold is −35 dBFS. The tool prints a hint with the track's measured level; raise the threshold (
silence.py --threshold -25) or shorten--min-silence. - Sync results carry a confidence. Below 0.3, or an offset near the edge of the analysis window, is probably wrong: enlarge
--analyze-secondsor find a clap. Recordings over ten minutes from separate devices needsync.py --fix-drift. - Outputs are never overwritten silently. An existing output path is refused (
kind: input, before anything runs); pass--overwritewhere a replacement is intended. - Long chains belong in a plan. Three hand-chained re-encodes lose quality and are hard to change;
render.pyruns the whole edit from one JSON file, and--dry-runshows every ffmpeg command before anything is written.
FFmpeg compatibility
// faq
What is ffmpeg-skill?
Local video editor for coding agents: 42 FFmpeg tools with a machine-readable contract and an MCP server, for Claude Code, Cursor and Codex. Cut, captions, reframe, loudness, platform exports. No cloud, no API keys.. It is open-source on GitHub.
Is ffmpeg-skill free to use?
ffmpeg-skill is open-source under the MIT license, so it is free to use.
What category does ffmpeg-skill belong to?
ffmpeg-skill is listed under mcp-servers in the Claudeers registry of Claude-compatible tools.
// embed badge

[](https://claudeers.com/ffmpeg-skill)
// retro hit counter

[](https://claudeers.com/ffmpeg-skill)
// reviews
// guestbook
// related in MCP Servers
 🔓
f.k.a. Awesome ChatGPT Prompts. Share, discover, and collect prompts from the community. Free and open source — self-host for your organization with complete…
 🔓
A cross-platform desktop All-in-One assistant for Claude Code, Codex, OpenCode, OpenClaw, Gemini CLI & Hermes Agent. Only official website: ccswitch.io
 🔓
🪨 why use many token when few token do trick — Claude Code skill that cuts 65% of tokens by talking like caveman
 🔓
An open-source AI agent that brings the power of Gemini directly into your terminal.
// compare ffmpeg-skill with
// built by
1 of its contributors also build on official projects — claude-code, claude-cookbooks, claude-plugins-official
→ see how ffmpeg-skill connects across the ecosystem